agentset
The open-source RAG platform: built-in citations, deep research, 22+ file formats, partitions, MCP server, and more.
Runs with mockssource: GitHubhomepageTypeScriptMITcommit 03283cc6383b
TypeScript, MIT licensed. The project labels itself: agentic rag, ai, ai agents, ai sdk, chatbots, embeddings, genai and llms.
agentset runs, with stand-ins for the services it depends on. An Argusic agent installed it in 25 minutes and hit 5 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
Agentset monorepo installs dependencies with bun 1.4.2 (using Bun's bundled Node 26.3.0), generates Prisma client with all enums, and passes 616 of 643 tests across web and engine packages.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 56 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
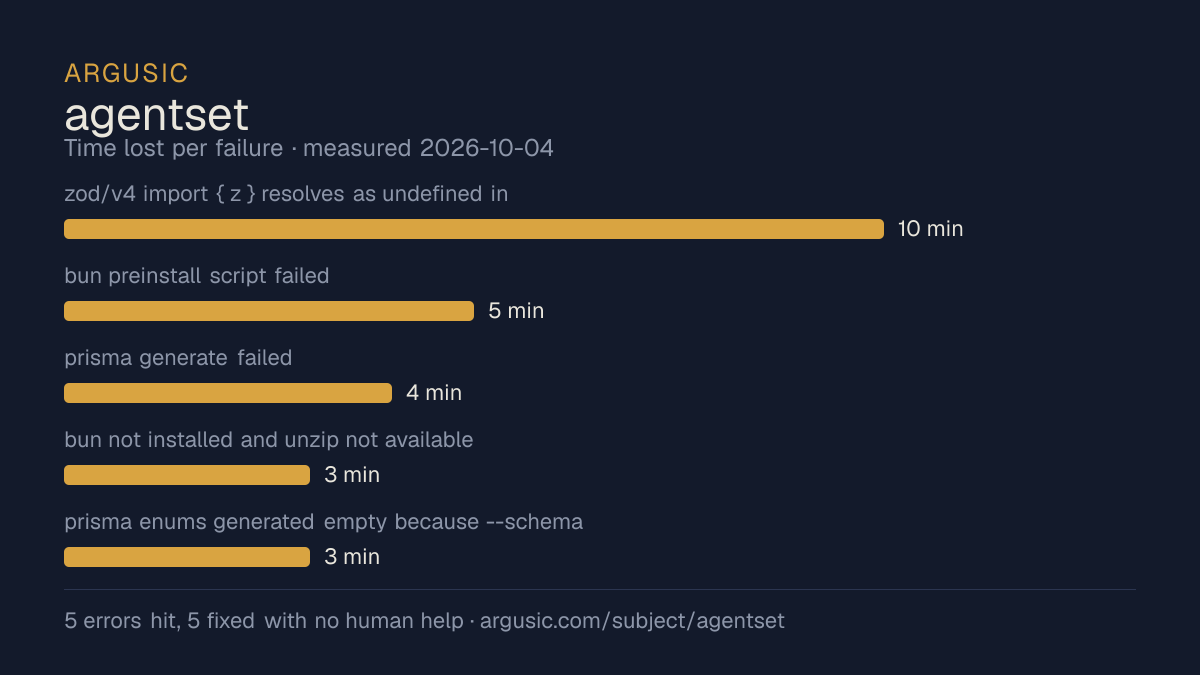
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- zod/v4 import { z } resolves as undefined in vitest/vite due to chained re-export of namespace import10 minutes
- bun preinstall script failed: Prisma requires Node >=22.12 but system has Node 18.19.15 minutes
- prisma generate failed: missing DIRECT_URL env var; schema file needed explicit path4 minutes
- bun not installed and unzip not available3 minutes
- prisma enums generated empty because --schema pointed to single file instead of directory3 minutes
- Install time
- 25 minutes
- Cold machine to finish
- 42 minutes
- Errors hit and fixed
- 5 hit, 5 fixed with no human help
- How the result was proved
- bun run --bun vitest run in apps/web: 445/463 passed, 31/33 test files passed; bun run --bun vitest run in packages/engine: 171/180 passed, 6/8 test files passed
- Model tokens used
- 555,140
- Exact commit tested
- 03283cc6383b
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
# Compute approximate total elapsed time
date +%s' in /work/repo
 succeeded in 0ms:
1791137106
exec
/bin/sh -lc 'export PATH="/tmp:$PATH"
# Start timestamp from the log and current time
echo "Session started ~17:24, ended ~18:03 UTC"' in /work/repo
 succeeded in 0ms:
Session started ~17:24, ended ~18:03 UTC
tokens used
555,140
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Installed in 25 minutes.
- Recovered from all 5 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed MIT, as reported by its host.
- Measured 2 times, so the result is not a one-off.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 2/3 | Runs with mocks | 92.00 | 0.22 | |
| Argusic Runner | 1/3 | Did not run | 20.00 | 0.07 |
Topics (from GitHub)
agentic-ragaiai-agentsai-sdkchatbotsembeddingsgenaillmsmemorymemory-managementragvercel-ai-sdk
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/agentset)Questions
- Does agentset run?
- agentset runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 25 minutes, hitting 5 errors on the way, and recorded the session.
- How did Argusic test agentset?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 03283cc6383b. 2 attempts are recorded, and the full method is on the methodology page.
- What did it cost to test agentset?
- The run that produced this verdict cost $0.22: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does agentset take to install?
- 25 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does agentset need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing agentset?
- 5 things broke in the recorded run, and 5 were fixed without human help. Each one, and the time it cost, is listed on this page.
- Where is the evidence for agentset?
- All 2 recorded runs are on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.