VoiceMem
Infrastructure for the next generation of voice agents, designed to provide universal memory. It is divided into a left brain and a right brain, storing information and emotions respectively, while a fully streaming architecture eliminates latency at the fundamental level.
Runs with mockssource: GitHubPythonApache-2.0commit 6cacb3c1e7fc
Python, Apache-2.0 licensed. The project labels itself: ai, ai agents, ai tools, application, audio streaming, genai, llm and long term memory.
VoiceMem runs, with stand-ins for the services it depends on. An Argusic agent installed it in 18 minutes and hit 6 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
VoiceMem 0.2.3 installed in Python 3.12 virtual environment at /tmp/venv; left-brain memory ingest/search pipeline functional with mock OpenAI API; 5/5 unit tests pass; audio perception models not downloaded (ASR/VAD warmup skipped gracefully); PortAudio-dependent capture unavailable (no root).
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
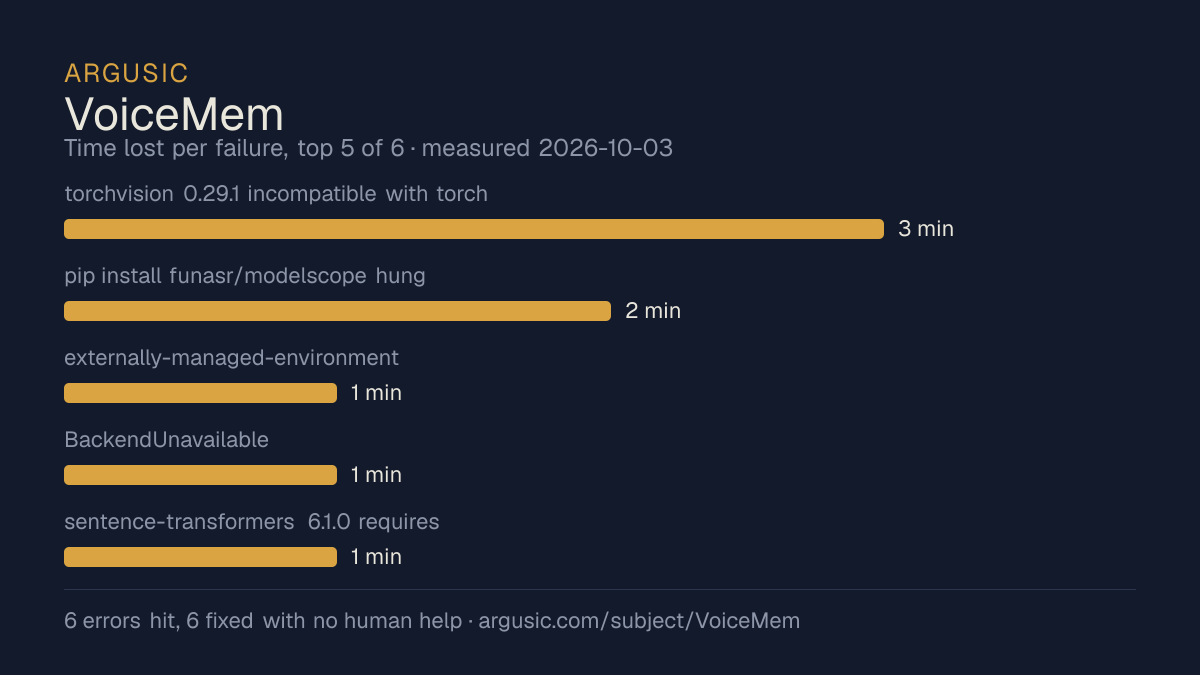
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- torchvision 0.29.1 incompatible with torch 2.13.0 (RuntimeError: operator torchvision::nms does not exist)3 minutes
- pip install funasr/modelscope hung (corrupted pip cache)2 minutes
- externally-managed-environment: system Python 3.12 blocks system-wide pip install (PEP 668)1 minute
- BackendUnavailable: Cannot import 'setuptools.build_meta' (setuptools not in fresh venv)1 minute
- sentence-transformers 6.1.0 requires transformers>=5.0.0, conflicting with pinned transformers==4.52.31 minute
- sounddevice requires PortAudio system library (OSError: PortAudio library not found)
- Install time
- 18 minutes
- Cold machine to finish
- 15 minutes
- Errors hit and fixed
- 6 hit, 6 fixed with no human help
- How the result was proved
- cd /work/repo && /tmp/venv/bin/python -m unittest tests.test_offline_engine tests.test_session_context -v -> 5 tests pass (0.054s); standalone mock-API integration test confirmed 2 facts ingested and retrieved via semantic search
- Model tokens used
- 77,672
- Exact commit tested
- 6cacb3c1e7fc
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
- Created `/tmp/venv` virtual environment (system Python 3.12 blocks pip system-wide)
- Installed all dependencies individually to avoid pip resolver hangs
- Fixed torchvision version incompatibility (`0.29.1` → `0.28.0` for torch 2.13.0)
- Fixed sentence-transformers version conflict (`6.1.0` → `5.7.0`)
- Installed `voicemem` in editable mode
**Verification:**
- **5/5 unit tests pass** (3 right-brain reaction/trait tests, 2 session context tests)
- Full **ingest → search pipeline verified** with mock Argusic API: 2 facts ingested, local E5 sema…
- Core modules (`VoiceMem`, `LeftBrain`, `RightBrain`, `Orchestrator`, etc.) import cleanly
- Web demo modules import successfully
- `sounddevice`/PortAudio unavailable without root (expected)
- Audio perception model downloads not present (ASR/VAD warmup skipped gracefully)
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Recovered from all 6 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed Apache-2.0, as reported by its host.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Took 18 minutes to install, slower than the median of the 80 comparable projects Argusic has measured.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Of the 81 ai projects Argusic has installed and timed, VoiceMem was the 67th fastest to reach a running state, and 56 of 81 reached one at all.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.07 |
Topics (from GitHub)
aiai-agentsai-toolsapplicationaudio-streaminggenaillmlong-term-memorymemorymemory-managementpythonvoice-agentvoice-assistant
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/voicemem)Questions
- Does VoiceMem run?
- VoiceMem runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 18 minutes, hitting 6 errors on the way, and recorded the session.
- How did Argusic test VoiceMem?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 6cacb3c1e7fc. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test VoiceMem?
- The run that produced this verdict cost $0.07: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does VoiceMem take to install?
- 18 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does VoiceMem need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing VoiceMem?
- 6 things broke in the recorded run, and 6 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does VoiceMem compare with the alternatives?
- Of the 81 ai projects Argusic has installed and timed, VoiceMem was the 67th fastest to reach a running state, and 56 of 81 reached one at all.
- Where is the evidence for VoiceMem?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.