memoket-kite
An open-source, vector-free long-term memory engine for AI agents, achieving SOTA on LoCoMo and LongMemEval with significantly less context.
Runs with mockssource: GitHubhomepagePythonApache-2.0commit c007108f926d
Python, Apache-2.0 licensed. The project labels itself: agent memory, agents, ai, ai agents, ai memory, chatbot, genai and knowledge management.
memoket-kite runs, with stand-ins for the services it depends on. An Argusic agent installed it in 16 minutes and hit 3 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
memoket-kite 0.1.0 is installed with all dependencies in a Python venv, 425/427 tests pass, and the full Memory remember/recall/answer pipeline executes correctly against a mock OpenAI-compatible provider
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
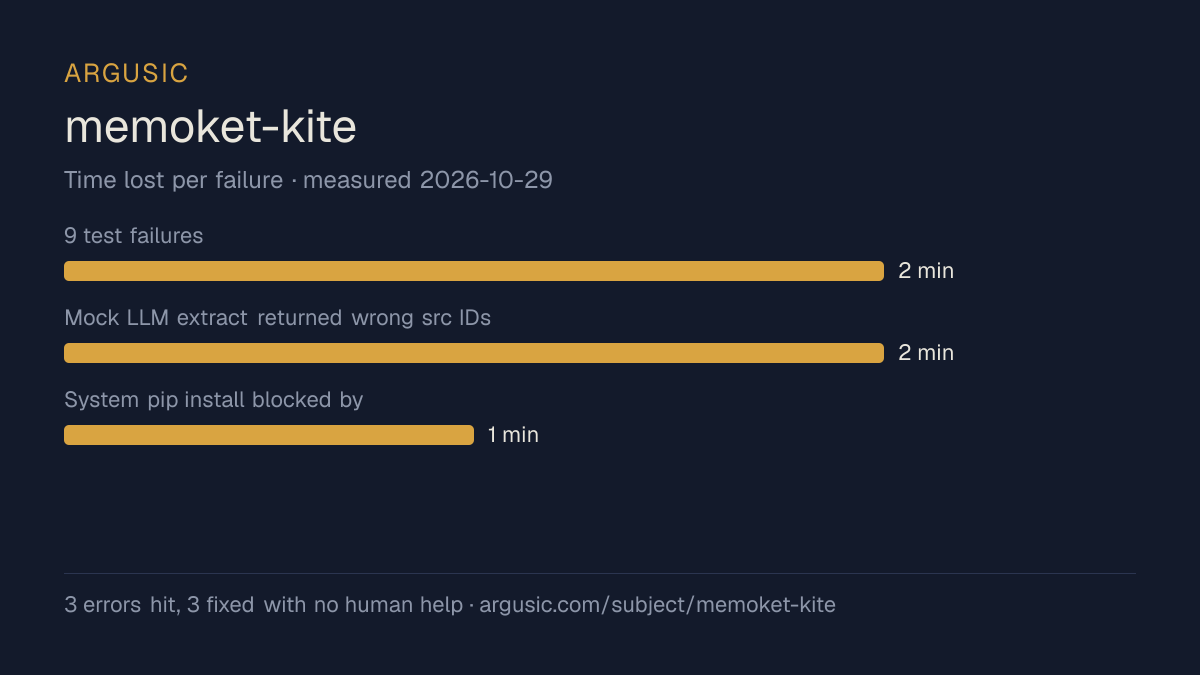
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- 9 test failures: o200k_base tokenizer encoding unavailable (tiktoken not installed)2 minutes
- Mock LLM extract returned wrong src IDs (regex captured whole | delimited line)2 minutes
- System pip install blocked by externally-managed-environment1 minute
- Install time
- 16 minutes
- Cold machine to finish
- 17 minutes
- Errors hit and fixed
- 3 hit, 3 fixed with no human help
- How the result was proved
- pip install -e succeeded; pytest: 425 passed / 2 skipped; full quickstart pipeline (remember+recall+answer_with_evidence) verified via mock LLM server returning correct plan/extraction JSON
- Model tokens used
- 398,675
- Exact commit tested
- c007108f926d
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
|---|---|---|
| System pip blocked by `externally-managed-environment` | Created and used a Python venv | 1 min |
| 9 test failures — `tiktoken` (o200k_base) not installed for exact token counting | Installed the …
| Mock LLM extract returned source IDs as `session_1L1\|user\|` instead of `session_1L1` | Fixed re…
### What was verified
- **Test suite**: `python -m pytest tests/ -q` → **425 passed, 2 skipped** (2 skips are expected: h…
- **Full quickstart pipeline** (via mock LLM server on `127.0.0.1:8999`):
  - `Memory.load()`, `remember()`, `recall()`, `answer_with_evidence()` all executed correctly
  - Fact extraction → XML persistence → recall → evidence-backed answer: round-trip verified
- **Inspect codebook example** ran without errors
### Limitations (tier2_mock)
The recall and answer flows require an LLM to compile natural-language questions into symbolic quer…
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Recovered from all 3 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed Apache-2.0, as reported by its host.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Took 16 minutes to install, slower than the median of the 22 comparable projects Argusic has measured.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Of the 23 agent-memory projects Argusic has installed and timed, memoket-kite was the 17th fastest to reach a running state, and 21 of 23 reached one at all.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.16 |
Topics (from GitHub)
agent-memoryagentsaiai-agentsai-memorychatbotgenaiknowledge-managementllmllm-memorylocomolong-term-memorylongmemevalmemorymemory-enginememory-layermemory-managementpythonragretrieval
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/memoket-kite)Questions
- Does memoket-kite run?
- memoket-kite runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 16 minutes, hitting 3 errors on the way, and recorded the session.
- How did Argusic test memoket-kite?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit c007108f926d. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test memoket-kite?
- The run that produced this verdict cost $0.16: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does memoket-kite take to install?
- 16 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does memoket-kite need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing memoket-kite?
- 3 things broke in the recorded run, and 3 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does memoket-kite compare with the alternatives?
- Of the 23 agent-memory projects Argusic has installed and timed, memoket-kite was the 17th fastest to reach a running state, and 21 of 23 reached one at all.
- Where is the evidence for memoket-kite?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.