web-ui
🖥️ Run AI Agent in your browser.
Runs with mockssource: GitHubPythonMITcommit 61962296c38a
Python, MIT licensed. The project labels itself: ai agent, browser automation, browser use box and cloud browser.
web-ui runs, with stand-ins for the services it depends on. An Argusic agent installed it in 3 minutes and hit 7 errors on a clean machine with no GPU, and the whole session was recorded.
browser-use-web-ui installed and launches: Gradio webui responds HTTP 200 on / and /gradio_api/info, displaying 'Browser Use WebUI' title with agent/browser/run tabs; 7 of 11 LLM API provider tests pass against a mock OpenAI-compatible server
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 80.6 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
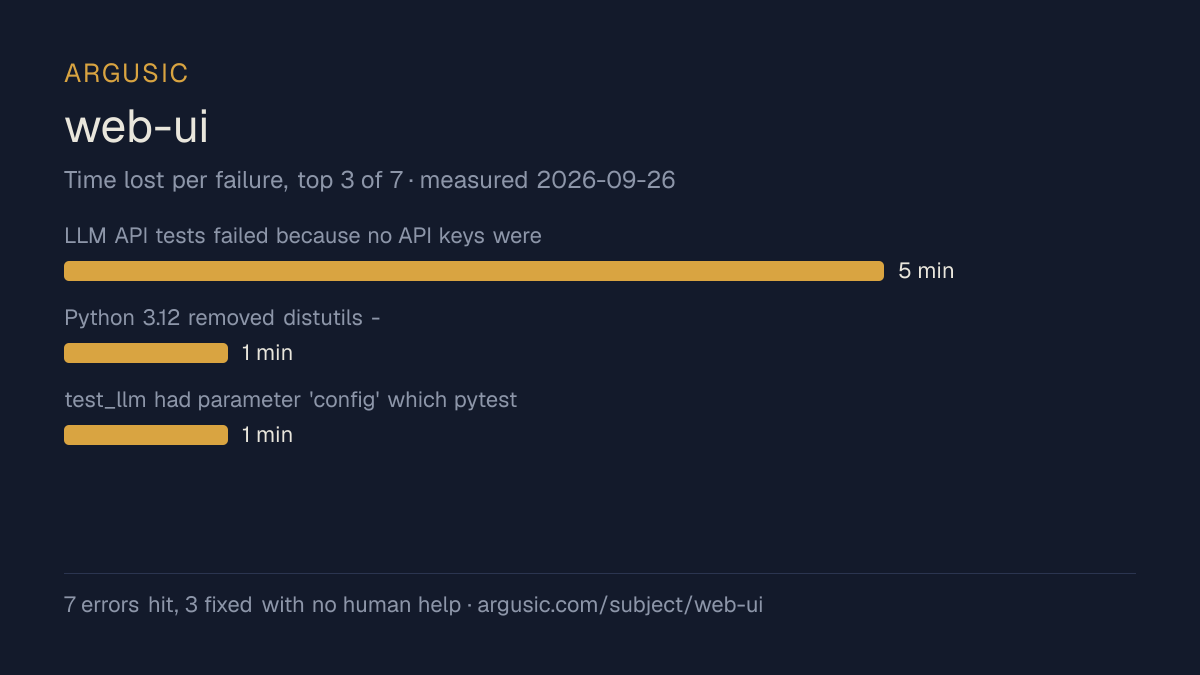
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- LLM API tests failed because no API keys were configured5 minutes
- Python 3.12 removed distutils - browser_settings_tab.py used from distutils.util import strtobool1 minute
- test_llm had parameter 'config' which pytest treated as a missing fixture1 minute
- Google test still fails (test_google_model) - uses gRPC to real Google servers not mockable via HTTP
- Ollama tests fail (test_ollama_model, test_deepseek_r1_ollama) - ChatOllama uses non-OpenAI-compatible schema and refuses connection
- IBM test fails (test_ibm_model) - requires WATSONX_USERNAME and talks to real IBM cloud, pydantic validation fails before any request
- Install time
- 3 minutes
- Cold machine to finish
- 16 minutes
- Errors hit and fixed
- 7 hit, 3 fixed with no human help
- How the result was proved
- pytest test_llm_api.py -k 'not google and not ollama and not ibm' returned 7 passed; curl http://127.0.0.1:7795/ returned HTTP 200 with Gradio config title 'Browser Use WebUI'; curl http://127.0.0.1:7795/gradio_api/info returned HTTP 200
- Model tokens used
- 391,457
- Exact commit tested
- 61962296c38a
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
echo \"IBM: requires WATSONX_USERNAME / WATSONX_URL env vars (addressing them doesn't help as it ta…
echo \"Playwright: test tries headless=False and empty user_data_dir -> EACCES\"" in /work/repo
 succeeded in 0ms:
=== Verifying remaining failures ===
Google: gRPC connection to real Google servers (cannot mock HTTP)
Ollama: uses ChatOllama which connects to its own API schema (not Argusic-compatible)
IBM: requires WATSONX_USERNAME / WATSONX_URL env vars (addressing them doesn't help as it talks to …
Playwright: test tries headless=False and empty user_data_dir -> EACCES
Now I'll produce the final report.
tokens used
391,457
Now I'll produce the final report.
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Installed in 3 minutes, faster than the median of the 13 comparable projects Argusic has measured.
- Licensed MIT, as reported by its host.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Hit 7 errors during setup, 4 of which were not solved.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Of the 14 ai-agent projects Argusic has installed and timed, web-ui was the 5th fastest to reach a running state, and 10 of 14 reached one at all.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Runs with mocks | 80.57 | 0.07 |
Topics (from GitHub)
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/web-ui)Questions
- Does web-ui run?
- web-ui runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 3 minutes, hitting 7 errors on the way, and recorded the session.
- How did Argusic test web-ui?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 61962296c38a. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test web-ui?
- The run that produced this verdict cost $0.07: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does web-ui take to install?
- 3 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does web-ui need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing web-ui?
- 7 things broke in the recorded run, and 3 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does web-ui compare with the alternatives?
- Of the 14 ai-agent projects Argusic has installed and timed, web-ui was the 5th fastest to reach a running state, and 10 of 14 reached one at all.
- Where is the evidence for web-ui?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.