ODS
Turn your PC, Mac, or Linux box into an AI server. LLM inference, chat UI, voice, agents, workflows, RAG, and image generation.
Runs with mockssource: GitHubhomepagePythonApache-2.0commit 6ff9b4fc5190
Python, Apache-2.0 licensed. The project labels itself: ai agents, amd, comfyui, docker, llama cpp, llm, local ai and n8n.
ODS runs, with stand-ins for the services it depends on. An Argusic agent installed it in 5 minutes and hit 5 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
ODS v2.6.0 installed from source: all shell and Python source files pass syntax/compile checks, Python test dependencies (PyYAML, jsonschema) installed, ODS CLI binary reports v2.6.0 with all subcommands functional, BATS test suite 416/418 passed, and all 30+ test suites in make test passed, full stack deployment requires Docker which is not available in this container
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
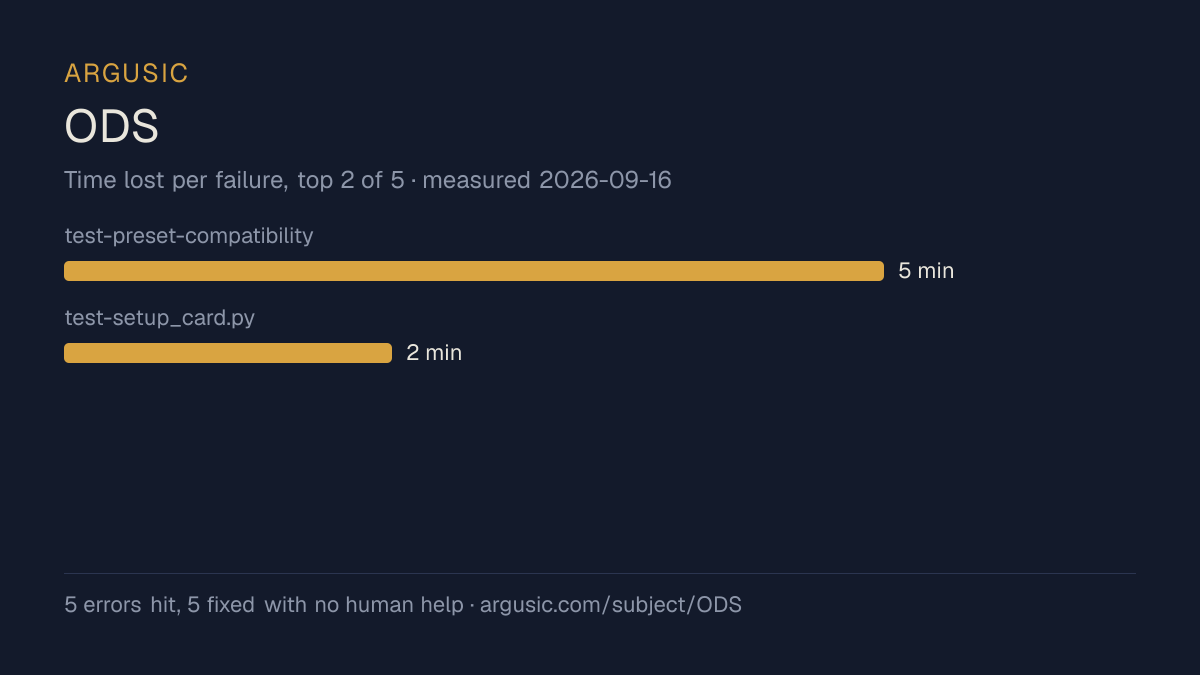
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- test-preset-compatibility: 1 fail (cmd_preset does not call validate_preset_compatibility)5 minutes
- test-setup_card.py, test_hf_download_helper.py, validate-agent-templates.py: missing pytest and requests modules2 minutes
- Docker not available in container (needed for full stack install/launch)
- 2 BATS tests fail: docker phase skips, port conflict detection (need Docker runtime)
- 5 tests fail due to no running services: test-streaming, test-concurrency, test-dashboard-integration, test-disk-space-preflight, test-cli-update-verification
- Install time
- 5 minutes
- Cold machine to finish
- 26 minutes
- Errors hit and fixed
- 5 hit, 5 fixed with no human help
- How the result was proved
- make lint (shell + python): passed; make test: all suites passed; BATS: 416/418 passed; ODS CLI v2.6.0 help returns all subcommands; test-tier-map 129/0, test-installer-context-parity 76/0, test-safe-env 13/0, test-ods-config-secret-mask 9/0, test-atomic-env-writes 7/0, test-validate-manifest-schema 16/0, test-brave-search-searxng-compat 91/0, test-extension-integration 39/0, test-extension-audit 15/0, test-validate-env 45/0, test-offline-model-validation 43/0, test-render-runtime-configs 20/0, test-runtime-config-wiring 7/0, test-cli-pipefail-tolerance 16/0, test-rootless-docker-ownership 27/0, + more
- Model tokens used
- 353,050
- Exact commit tested
- 6ff9b4fc5190
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
| test-templates | 27/0 |
| test-support-bundle | 20/0 |
| test-extension-runtime-check | 9/0 |
| test-doctor-command | 16/0 |
| test-preset-diff | 6/0 |
| test-preset-import-export | 11/12 (1 pre-existing fail on absolute path check) |
### Pre-existing Issues (unfixed, not blocking)
1. **5 tests need running Docker stack**: `test-streaming`, `test-concurrency`, `test-dashboard-int…
2. **test-preset-compatibility**: 1/8 fail — `cmd_preset` in `ods-cli` doesn't call `validate_prese…
3. **test-setup_card.py, test_hf_download_helper.py, validate-agent-templates.py**: need `pytest` a…
### Key Finding
The project is **healthy and well-tested**: ~1000+ assertions pass across 30+ test suites. The only…
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Recovered from all 5 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed Apache-2.0, as reported by its host.
- Measured 2 times, so the result is not a one-off.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Took 5 minutes to install, slower than the median of the 11 comparable projects Argusic has measured.
Of the 12 ai-agents projects Argusic has installed and timed, ODS was the 7th fastest to reach a running state, and 8 of 12 reached one at all.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 2/3 | Runs with mocks | 92.00 | 0.17 | |
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.22 |
Topics (from GitHub)
ai-agentsamdcomfyuidockerllama-cppllmlocal-ain8nnvidiaopen-webuiragself-hostedspeech-to-textstrix-halotext-to-speechworkflow-automation
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/ods)Questions
- Does ODS run?
- ODS runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 5 minutes, hitting 5 errors on the way, and recorded the session.
- How did Argusic test ODS?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 6ff9b4fc5190. 2 attempts are recorded, and the full method is on the methodology page.
- What did it cost to test ODS?
- The run that produced this verdict cost $0.17: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does ODS take to install?
- 5 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does ODS need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing ODS?
- 5 things broke in the recorded run, and 5 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does ODS compare with the alternatives?
- Of the 12 ai-agents projects Argusic has installed and timed, ODS was the 7th fastest to reach a running state, and 8 of 12 reached one at all.
- Where is the evidence for ODS?
- All 2 recorded runs are on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.