AssetOpsBench
AssetOpsBench - Industry 4.0: A unified benchmark and framework for building, orchestrating, and evaluating domain-specific AI agents for Industry 4.0 asset operations and maintenance, with 460+ scenarios, 5 specialist agents (IoT, FMSR, TSFM, Work Order,...), and multi-agent orchestration blueprints (MetaAgent, AgentHive) over MCP.
Runs with mockssource: GitHubPythonApache-2.0commit 81265cbbd36d
Python, Apache-2.0 licensed. The project labels itself: ai for physical assets, condition based maintenance, hvac maintenance, iot, llm agents, model context protocol, predictive maintenance and time series forecasting.
AssetOpsBench runs, with stand-ins for the services it depends on. An Argusic agent installed it in 20 minutes and hit 5 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
Project installs, builds, and 675 of 702 tests pass; 27 integration tests skip due to missing CouchDB/LLM credentials; all CLI entry points import and display help.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
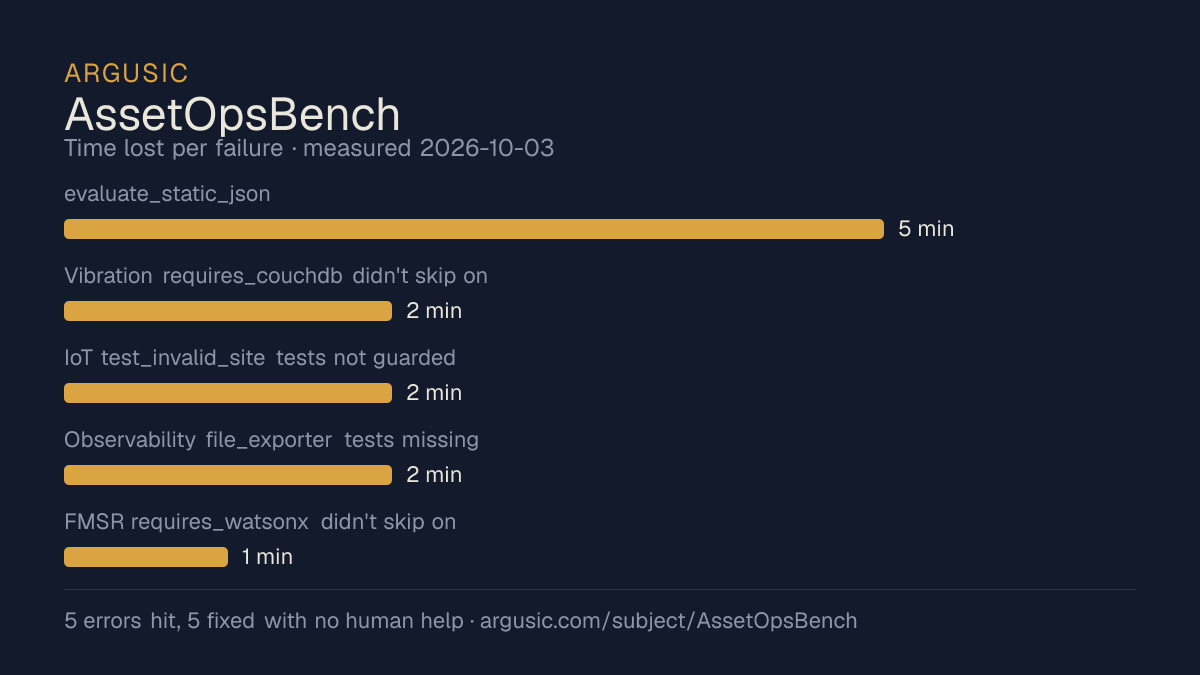
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- evaluate_static_json() got unexpected keyword argument 'evaluation_metadata'5 minutes
- Vibration requires_couchdb didn't skip on unreachable CouchDB (empty-string env var)2 minutes
- IoT test_invalid_site tests not guarded against missing CouchDB2 minutes
- Observability file_exporter tests missing google.protobuf and opentelemetry-exporter2 minutes
- FMSR requires_watsonx didn't skip on empty-string WATSONX_APIKEY1 minute
- Install time
- 20 minutes
- Cold machine to finish
- 25 minutes
- Errors hit and fixed
- 5 hit, 5 fixed with no human help
- How the result was proved
- pytest src/ --tb=line -q exited 0, 675 passed, 27 skipped
- Model tokens used
- 129,831
- Exact commit tested
- 81265cbbd36d
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
tokens used
129,831
**Final summary of what was done:**
1. **`uv sync`** completed successfully — all dependencies installed, `.venv` created with Python 3…
2. **Fixed test failures:**
   - **`static_json_scorer.py`** — Added `evaluation_metadata` parameter to `evaluate_static_json()…
   - **`vibration/tests/conftest.py`** — `requires_couchdb` marker now actually checks reachability…
   - **`fmsr/tests/conftest.py`** — `requires_watsonx` marker now uses truthiness instead of `is No…
   - **`iot/tests/test_tools.py`** — Added `@requires_couchdb` to 11 `test_invalid_site` methods th…
3. **Installed missing runtime deps:** `protobuf` and `opentelemetry-exporter-otlp-proto-http` for …
4. **Final test suite:** 675 passed, 27 skipped, 0 failed (27 skipped are CouchDB/LLM integration t…
5. **CLI entry points** all import correctly, `--help` commands work.
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Installed in 20 minutes.
- Recovered from all 5 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed Apache-2.0, as reported by its host.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.25 |
Topics (from GitHub)
ai-for-physical-assetscondition-based-maintenancehvac-maintenanceiotllm-agentsmodel-context-protocolpredictive-maintenancetime-series-forecasting
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/assetopsbench)Questions
- Does AssetOpsBench run?
- AssetOpsBench runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 20 minutes, hitting 5 errors on the way, and recorded the session.
- How did Argusic test AssetOpsBench?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 81265cbbd36d. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test AssetOpsBench?
- The run that produced this verdict cost $0.25: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does AssetOpsBench take to install?
- 20 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does AssetOpsBench need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing AssetOpsBench?
- 5 things broke in the recorded run, and 5 were fixed without human help. Each one, and the time it cost, is listed on this page.
- Where is the evidence for AssetOpsBench?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.