awesome-agentic-ai-zh
A trilingual (繁中 / English / 简中) learning roadmap for agentic AI: from LLM basics to multi-agent systems, with 240+ curated resources and hands-on examples. 中文 AI agent 學習地圖。
Runs with mockssource: GitHubhomepagePythonMITcommit dce3048e1f9f
Python, MIT licensed. The project labels itself: agentic ai, agentic workflows, ai agent, ai agents, awesome list, chinese llm, claude code and claude skills.
awesome-agentic-ai-zh runs, with stand-ins for the services it depends on. An Argusic agent installed it in 1 minute and hit 2 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
Mkdocs documentation site builds successfully (106M), all 1083 script-level tests pass, and all 51 offline example tests pass with mocked dependencies; the project is a learning roadmap with runnable exercises for LLM agent development across OpenAI, Anthropic, and Ollama-compatible providers.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
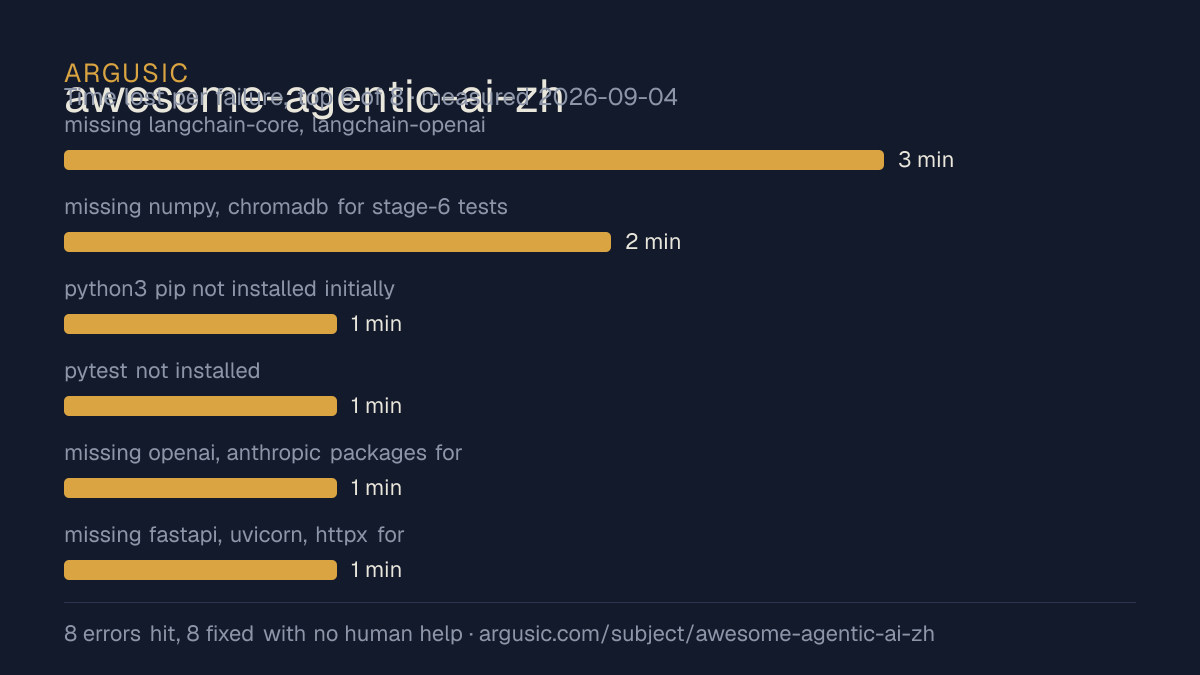
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- pip install pydantic-ai, chromadb, fastapi, smolagents missing for example tests3 minutes
- pip install opencc-python-reimplemented missing for scripts/test_hans_chars.py — 13 test failures2 minutes
- Install time
- 1 minutes
- Cold machine to finish
- 7 minutes
- Errors hit and fixed
- 2 hit, 2 fixed with no human help
- How the result was proved
- mkdocs build produced site/; pytest scripts/ passed 1083/1083; all 51 example test_*.py files exited 0 with mocked SDKs
- Model tokens used
- 53,187
- Exact commit tested
- dce3048e1f9f
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
Watch the session
The whole run, from a clean machine, at the speed it actually happened. Nothing is cut and nothing is sped up.
A recording of attempt 1, run . The verdict above comes from a different attempt, so read this as one session and not as the current result. The terminal recording it was made from is the evidence, stored with a sha256 fingerprint; the video is a rendering of it. Nothing loads from the video host until you press play.
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
}
```
exec
/bin/sh -lc "cat << 'ENDJSON'
ENDJSON" in /work/repo
 succeeded in 0ms:
exec
/bin/sh -lc "cd /work/repo && echo '{\"install_succeeded\": true, \"launch_succeeded\": true, \"ins…
 succeeded in 0ms:
{"install_succeeded": true, "launch_succeeded": true, "install_minutes": 1, "errors": [{"msg": "pip…
tokens used
53,187
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Installed in 1 minute, faster than the median of the 37 comparable projects Argusic has measured.
- Recovered from all 2 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed MIT, as reported by its host.
- Measured 2 times, so the result is not a one-off.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
Of the 38 agentic-ai projects Argusic has installed and timed, awesome-agentic-ai-zh was the 6th fastest to reach a running state, and 28 of 38 reached one at all.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 2/3 | Runs with mocks | 92.00 | 0.09 | |
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.09 |
Topics (from GitHub)
agentic-aiagentic-workflowsai-agentai-agentsawesome-listchinese-llmclaude-codeclaude-skillsclilearning-roadmapllmllm-agentsmcpmodel-context-protocolmulti-agent-systemsprompt-engineeringragtrilingualtutorial
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/awesome-agentic-ai-zh)Questions
- Does awesome-agentic-ai-zh run?
- awesome-agentic-ai-zh runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 1 minutes, hitting 2 errors on the way, and recorded the session.
- How did Argusic test awesome-agentic-ai-zh?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit dce3048e1f9f. 2 attempts are recorded, and the full method is on the methodology page.
- What did it cost to test awesome-agentic-ai-zh?
- The run that produced this verdict cost $0.09: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does awesome-agentic-ai-zh take to install?
- 1 minute in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does awesome-agentic-ai-zh need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing awesome-agentic-ai-zh?
- 2 things broke in the recorded run, and 2 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does awesome-agentic-ai-zh compare with the alternatives?
- Of the 38 agentic-ai projects Argusic has installed and timed, awesome-agentic-ai-zh was the 6th fastest to reach a running state, and 28 of 38 reached one at all.
- Where is the evidence for awesome-agentic-ai-zh?
- All 2 recorded runs are on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.