Trail-Code
Turbocharge Claude Code, Cursor, Codex, Gemini & every coding agent: faster, cheaper, with contextual understanding specific to your codebase.
Runssource: GitHubhomepageTypeScriptMITcommit 8dc7a63b26dc
TypeScript, MIT licensed. The project labels itself: ai agents, anthropic, claude code, cli, code graph, codex, context engineering and cursor.
Trail-Code runs. An Argusic agent installed it in 14 minutes and hit 3 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
The graft CLI installs, builds, and its full test suite passes (1491/1492, 1 deliberate skip) with both previously-failing shim-resolution and lock-release tests green, and the CLI builds/parses/queries a scratch repo and completes an LLM deep pass against a local mock endpoint.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 100 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
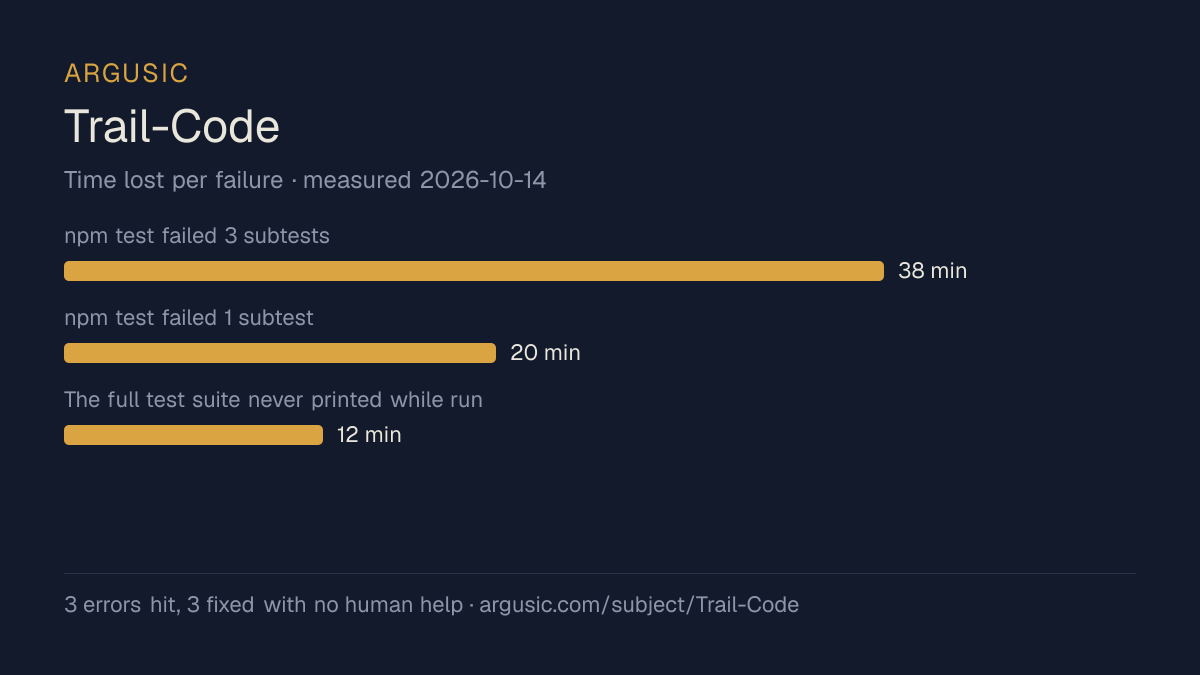
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- npm test failed 3 subtests: "the remembered install still wins when it is the newest" and "a single candidate is used whatever its version" (test/claude-shim-resolve.test.ts) because the shim rejected the remembered-install hint file (mode 664, group-writable under umask 002) despite same-uid ownership, silently dropping the remembered candidate38 minutes
- npm test failed 1 subtest: "a process killed while holding the lock releases it" (test/graph-refresh.test.ts) — the spawned `node -e` child died with SyntaxError "await is only valid in async functions" on Node 18, which runs -e as CommonJS20 minutes
- The full test suite never printed while run through `npm test` redirected to a file in this shell because the runner's buffered output stayed empty and a child from test/viz-serve.test.ts wedged in ep_poll for ~22 minutes (an environment quirk, not a repo error); I diagnosed it via /proc and terminated the wedged child12 minutes
- Install time
- 14 minutes
- Cold machine to finish
- 87 minutes
- Errors hit and fixed
- 3 hit, 3 fixed with no human help
- How the result was proved
- npm run build exited 0; node --import tsx --test test/*.test.ts printed '# tests 1492 / # pass 1491 / # fail 0'; node dist/cli.js --version printed 0.21.1; node dist/cli.js build . printed 'wiring: 4 nodes... 2 edges'; check --json returned context.ok true; deep build hit the mock (http code 200) and returned meaning: 3 computed
- Model tokens used
- 3,738,875
- Exact commit tested
- 8dc7a63b26dc
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
lock: dist/cli.js | package: dist/bin/graft.js
exec
/bin/sh -lc 'cd /work/repo && node --import tsx --test test/claude-shim-resolve.test.ts test/claude…
 succeeded in 5530ms:
# tests 46
# pass 46
# fail 0
# skipped 0
All clean. Final state verified. Here is the one-line report, per the required format:
tokens used
3,738,875
All clean. Final state verified. Here is the one-line report, per the required format:
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Reached a running state on a clean machine, with the session recorded.
- Recovered from all 3 errors without a human stepping in, which says the failures are documented well enough to solve.
- Ran without a GPU, so it does not need one to start.
- Licensed MIT, as reported by its host.
What did not, or is not known
- Took 14 minutes to install, slower than the median of the 68 comparable projects Argusic has measured.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Of the 69 ai-agents projects Argusic has installed and timed, Trail-Code was the 47th fastest to reach a running state, and 53 of 69 reached one at all.
What it is a reasonable choice for
- Trying it on a laptop or a small server: it reached a running state without a GPU.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
Topics (from GitHub)
ai-agentsanthropicclaude-codeclicode-graphcodexcontext-engineeringcursordeveloper-toolsgeminiknowledge-graphllmmcpmcp-serveropen-sourceopenaitree-sitter
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/trail-code)Questions
- Does Trail-Code run?
- Yes. Trail-Code runs. Argusic installed and launched it on a clean machine in 14 minutes, hitting 3 errors on the way, and recorded the session.
- How did Argusic test Trail-Code?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 8dc7a63b26dc. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test Trail-Code?
- The run that produced this verdict cost $0.88: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does Trail-Code take to install?
- 14 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does Trail-Code need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing Trail-Code?
- 3 things broke in the recorded run, and 3 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does Trail-Code compare with the alternatives?
- Of the 69 ai-agents projects Argusic has installed and timed, Trail-Code was the 47th fastest to reach a running state, and 53 of 69 reached one at all.
- Where is the evidence for Trail-Code?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.