parlant
Parlant is an open platform for building customer-facing chat agents with AI. Describe how the agent should behave, and your coding agent implements it for you.
Runs with mockssource: GitHubhomepagePythonApache-2.0commit ea737442b8ae
Python, Apache-2.0 licensed. The project labels itself: ai agent, customer experience, customer service, customer success, lead generation, llm and python.
parlant runs, with stand-ins for the services it depends on. An Argusic agent installed it in 12 minutes and hit 8 errors on a clean machine with no GPU, and the whole session was recorded.
With a schema-correct mock NLP backend, the Parlant server started on port 18999, answered /healthz 200, created agents/guidelines/sessions (201), and ran the engine to completion status; 208 API tests passed while the parlant CLI remained unimportable.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 86.2 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
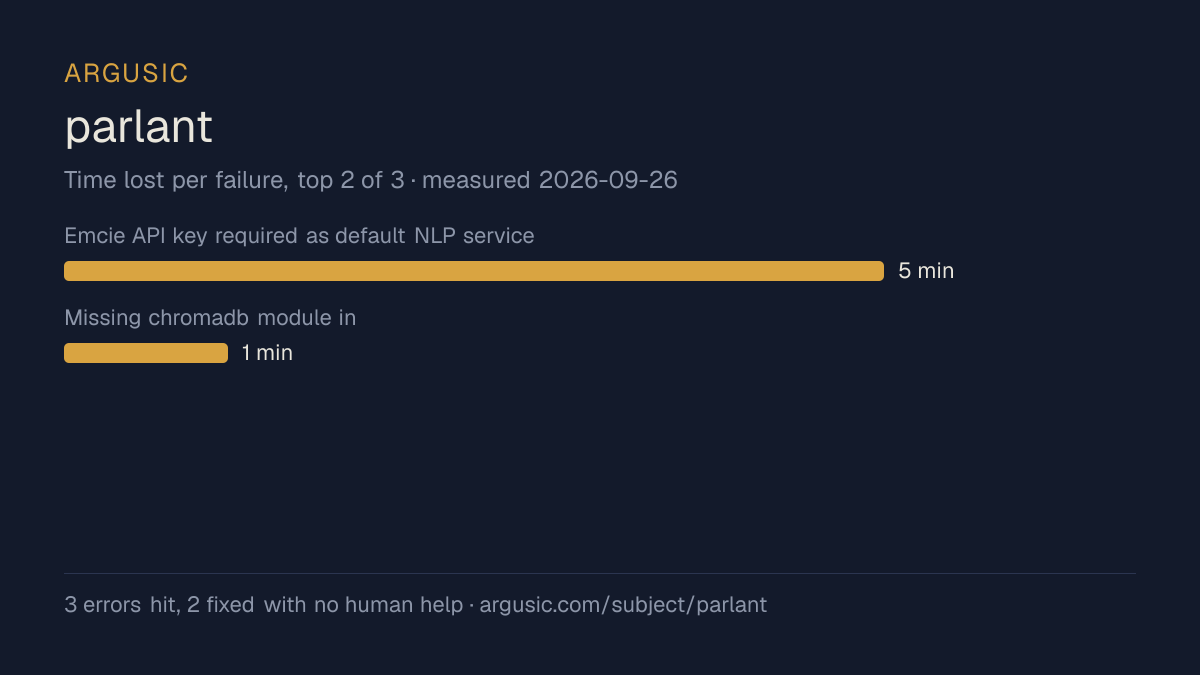
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- parlant CLI fails: ImportError cannot import JourneyTriggerUpdateParams from parlant.client.types12 minutes
- Tests failed with KeyError('EMCIE_API_KEY') because tests/conftest.py hardcodes EmcieService8 minutes
- pytest collection failed on missing qdrant_client, chroma, pymongo, litellm, azure, zhipuai modules4 minutes
- README claims OpenAI is the default NLP provider but p.Server() defaults to NLPServices.emcie and fails without EMCIE_API_KEY4 minutes
- Embedding dimension mismatch (128 mock dims vs 3072 expected)3 minutes
- test_embedding/test_generation fail: HealthReporter.__init__() missing required positional argument application_context3 minutes
- Install time
- 12 minutes
- Cold machine to finish
- 54 minutes
- Errors hit and fixed
- 8 hit, 6 fixed with no human help
- How the result was proved
- curl -s -o /dev/null -w %{http_code} localhost:18999/healthz returned 200; POST /agents returned 201; POST /sessions returned 201; engine emitted acknowledged/processing/typing/ready status events; pytest run with mock Emcie/OpenAI servers reported '208 passed' on API modules and '229 passed, 1 failed' on the mixed suite; uv run parlant-server run --version printed 'Parlant v3.3.1'
- Model tokens used
- 899,179
- Exact commit tested
- ea737442b8ae
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
899,179
All work is complete. Summary of what I observed, followed by the required result line.
**What worked**
- `uv sync --group dev --extra chroma --extra mongo --extra qdrant --extra litellm --extra azure --…
- `uv run parlant-server run --version` printed `Parlant v3.3.1`.
- Server launched against a schema-correct Argusic-compatible mock: `GET /healthz`→200, `GET /agent…
- README SDK flow (`p.Server(nlp_service=p.NLPServices.openai)` + `create_agent`) created an agent …
- Test suite with in-process schema-correct Emcie mock: 208 API tests passed, 0 failed; 229 passed …
**Unresolved**
- `parlant` CLI crashes on import: `parlant-client` pinned at v3.2.0 lacks `JourneyTriggerUpdatePar…
- README states Argusic is the default NLP provider, but `p.Server()` actually defaults to `NLPServ…
- Some tests call `HealthReporter()` without the now-required `application_context`.
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Licensed Apache-2.0, as reported by its host.
- Measured 2 times, so the result is not a one-off.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Took 12 minutes to install, slower than the median of the 117 comparable projects Argusic has measured.
- Hit 8 errors during setup, 2 of which were not solved.
Of the 118 ai-agents projects Argusic has installed and timed, parlant was the 81st fastest to reach a running state, and 88 of 118 reached one at all.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 2/3 | Runs with mocks | 87.00 | 1.05 | |
| Argusic Runner | 1/3 | Runs with mocks | 85.33 | 0.17 |
Topics (from GitHub)
ai-agentcustomer-experiencecustomer-servicecustomer-successlead-generationllmpython
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/parlant)Questions
- Does parlant run?
- parlant runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 12 minutes, hitting 8 errors on the way, and recorded the session.
- How did Argusic test parlant?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit ea737442b8ae. 2 attempts are recorded, and the full method is on the methodology page.
- What did it cost to test parlant?
- The run that produced this verdict cost $1.05: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does parlant take to install?
- 12 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does parlant need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing parlant?
- 8 things broke in the recorded run, and 6 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does parlant compare with the alternatives?
- Of the 118 ai-agents projects Argusic has installed and timed, parlant was the 81st fastest to reach a running state, and 88 of 118 reached one at all.
- Where is the evidence for parlant?
- All 2 recorded runs are on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.