qwengate
Drop-in OpenAI-compatible API gateway for Qwen AI models. Use your Qwen account (chat.qwen.ai) as a free AI API provider in any OpenAI-compatible client, Cursor, Continue.dev, Claude Code, VS Code Copilot, or any coding agent. Self-hosted, Chromium-based auth, streaming support, tool calling, dashboard.
Runs with mockssource: GitHubhomepageTypeScriptMITcommit 5220f7d3c50c
TypeScript, MIT licensed. The project labels itself: ai proxy, api gateway, chat gateway, chromium, coding agent, free api, llm proxy and openai compatible.
qwengate runs, with stand-ins for the services it depends on. An Argusic agent installed it in 45 minutes and hit 3 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
Qwen Gate installs and builds cleanly, serves /health and /dashboard with 200, and completes a full chat-completion request end-to-end against a local schema-correct mock of chat.qwen.ai, with streaming SSE terminating in data: [DONE].
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
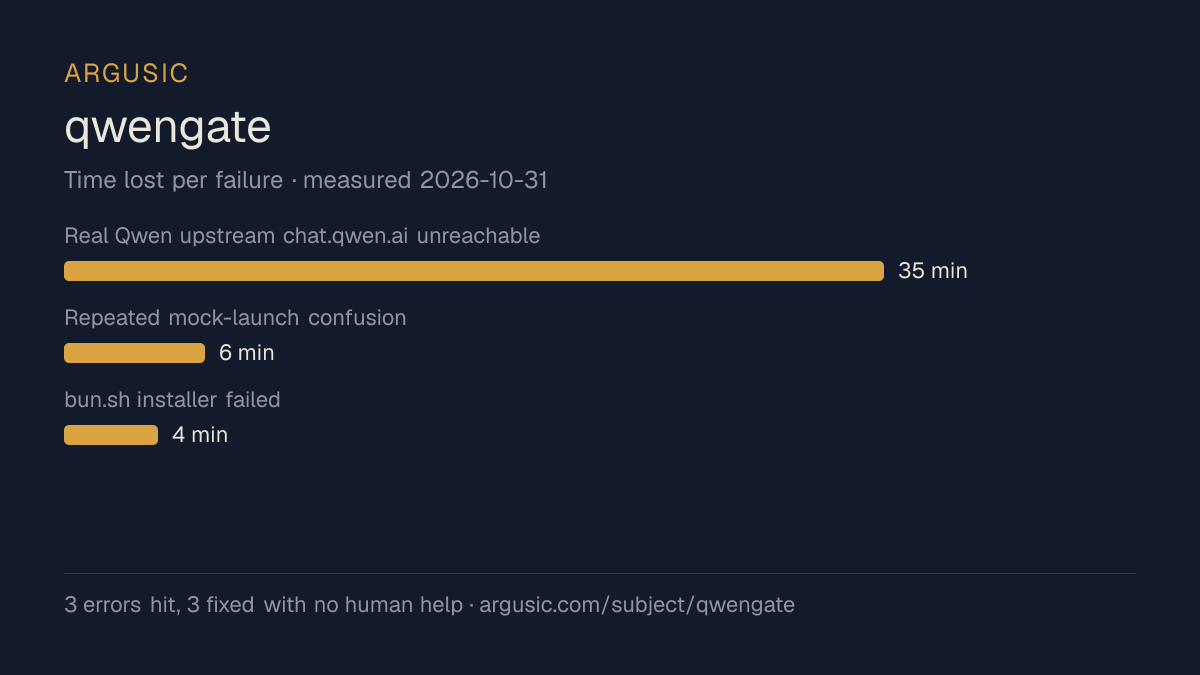
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- Real Qwen upstream chat.qwen.ai unreachable: WAF/connection and no Playwright browsers or Qwen credentials, so /v1/chat/completions returned 500 "Cookie refresh failed"35 minutes
- Repeated mock-launch confusion: & backgrounded processes died across shells and a stale regenerated placeholder entry pointed at real chat.qwen.ai6 minutes
- bun.sh installer failed: unzip not installed and no root4 minutes
- Install time
- 45 minutes
- Cold machine to finish
- 20 minutes
- Errors hit and fixed
- 3 hit, 3 fixed with no human help
- How the result was proved
- curl -s -w '%{http_code}' http://127.0.0.1:26405/health returned 200; curl /v1/models returned 200 with the two models served by the local mock; curl -N -X POST /v1/chat/completions with stream:true returned SSE chunks ending in 'data: [DONE]' while the mock inbox recorded POST /api/v2/chat/completions; bun test exited 0 with 154 pass, 0 fail
- Model tokens used
- 2,082,830
- Exact commit tested
- 5220f7d3c50c
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
I have all the evidence needed. Compiling the final report.
exec
/bin/sh -lc 'echo "final sanity: node_modules present, bun available, config exists"; test -d /work…
 succeeded in 0ms:
final sanity: node_modules present, bun available, config exists
node_modules OK
bun OK
config.json OK
mock processes:
0
tokens used
2,082,830
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Installed in 45 minutes.
- Recovered from all 3 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed MIT, as reported by its host.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.44 |
Topics (from GitHub)
ai-proxyapi-gatewaychat-gatewaychromiumcoding-agentfree-apillm-proxyopenai-compatibleopenai-proxyqwenqwen-apiqwen-gateself-hostedstreamingtool-calling
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/qwengate)Questions
- Does qwengate run?
- qwengate runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 45 minutes, hitting 3 errors on the way, and recorded the session.
- How did Argusic test qwengate?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 5220f7d3c50c. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test qwengate?
- The run that produced this verdict cost $0.44: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does qwengate take to install?
- 45 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does qwengate need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing qwengate?
- 3 things broke in the recorded run, and 3 were fixed without human help. Each one, and the time it cost, is listed on this page.
- Where is the evidence for qwengate?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.