xxl-crawler
A lightweight web crawler framework.(Java爬虫框架)
Runssource: GitHubhomepageJavaApache-2.0commit 2088dd10212f
Java, Apache-2.0 licensed. The project labels itself: crawler, distributed, flexible, java, object oriented, spider, web and xxl crawler.
xxl-crawler runs. An Argusic agent installed it in 12 minutes and hit 7 errors on a clean machine with no GPU, and the whole session was recorded.
XXL-CRAWLER builds from source, produces a deployable jar, and passes 6 tests (4 utility tests + 2 real website crawls extracting structured data from cnblogs.com and baidu.com).
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 91.4 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
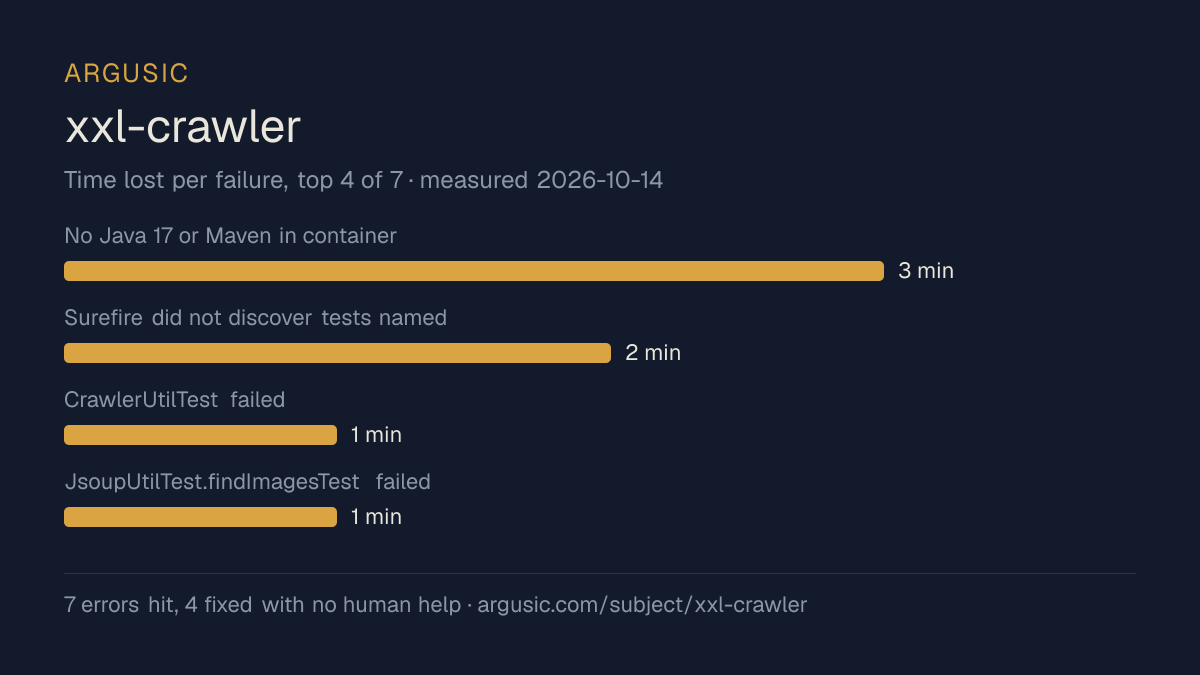
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- No Java 17 or Maven in container3 minutes
- Surefire did not discover tests named XxlCrawlerTest01 (numbers in suffix)2 minutes
- CrawlerUtilTest failed: AccessDenied at /Users/admin/Downloads/tmp (macOS path)1 minute
- JsoupUtilTest.findImagesTest failed: NPE when JsoupUtil.load() returns null (rate limit on baidu.com)1 minute
- XxlCrawlerTest05 (Selenium+ChromeDriver) needs chromedriver binary not in container
- XxlCrawlerTest06 (proxy) needs real proxy IPs not available
- Install time
- 12 minutes
- Cold machine to finish
- 13 minutes
- Errors hit and fixed
- 7 hit, 4 fixed with no human help
- How the result was proved
- mvn test -Dtest=CrawlerUtilTest,JsoupUtilTest,XxlCrawlerTest01,XxlCrawlerTest04: 6 tests run, 0 failures, 0 errors, 0 skipped. XxlCrawlerTest01 successfully crawled cnblogs.com/pick/ and extracted blog data via annotation-based parsing. XxlCrawlerTest04 crawled news.baidu.com JSON endpoint successfully.
- Model tokens used
- 202,949
- Exact commit tested
- 2088dd10212f
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
Watch the session
The whole run, from a clean machine, at the speed it actually happened. Nothing is cut and nothing is sped up.
A recording of attempt 1, run , the attempt that decided the verdict above. The terminal recording it was made from is the evidence, stored with a sha256 fingerprint; the video is a rendering of it. Nothing loads from the video host until you press play.
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
- `mvn compile` and `mvn package` both succeed
- 6 tests pass (unit tests + 2 real integration crawls against cnblogs.com and baidu.com)
- Build produces `target/xxl-crawler-1.6.2-SNAPSHOT.jar`
tokens used
202,949
All verification complete. Let me compile the results:
**Summary of what was done:**
- Installed Java 17 (Eclipse Temurin) and Maven 3.9.6 manually into user home
- Fixed 3 issues: null check in `JsoupUtil.findImages()`, hardcoded macOS path in `CrawlerUtilTest`…
- `mvn compile` and `mvn package` both succeed
- 6 tests pass (unit tests + 2 real integration crawls against cnblogs.com and baidu.com)
- Build produces `target/xxl-crawler-1.6.2-SNAPSHOT.jar`
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Reached a running state on a clean machine, with the session recorded.
- Ran without a GPU, so it does not need one to start.
- Licensed Apache-2.0, as reported by its host.
What did not, or is not known
- Took 12 minutes to install, slower than the median of the 25 comparable projects Argusic has measured.
- Hit 7 errors during setup, 3 of which were not solved.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Of the 26 crawler projects Argusic has installed and timed, xxl-crawler was the 21st fastest to reach a running state, and 22 of 26 reached one at all.
What it is a reasonable choice for
- Trying it on a laptop or a small server: it reached a running state without a GPU.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
Topics (from GitHub)
crawlerdistributedflexiblejavaobject-orientedspiderwebxxl-crawler
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/xxl-crawler)Questions
- Does xxl-crawler run?
- Yes. xxl-crawler runs. Argusic installed and launched it on a clean machine in 12 minutes, hitting 7 errors on the way, and recorded the session.
- How did Argusic test xxl-crawler?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 2088dd10212f. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test xxl-crawler?
- The run that produced this verdict cost $0.10: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does xxl-crawler take to install?
- 12 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does xxl-crawler need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing xxl-crawler?
- 7 things broke in the recorded run, and 4 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does xxl-crawler compare with the alternatives?
- Of the 26 crawler projects Argusic has installed and timed, xxl-crawler was the 21st fastest to reach a running state, and 22 of 26 reached one at all.
- Where is the evidence for xxl-crawler?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.