Unlimited-OCR
Unlimited OCR Works: Welcome the Era of One-shot Long-horizon Parsing.
Runs with mockssource: GitHubPythonMITcommit 92ad94b53a51
Python, MIT licensed.
Unlimited-OCR runs, with stand-ins for the services it depends on. An Argusic agent installed it in 8 minutes and hit 4 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
The Unlimited-OCR client (infer.py) installed and ran end-to-end against a schema-correct mock SGLang server, correctly processing 1 image and 14 PDF pages with streamed responses and writing all 15 markdown outputs; the real GPU SGLang server and real model weights were not run due to no accelerator in this container.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
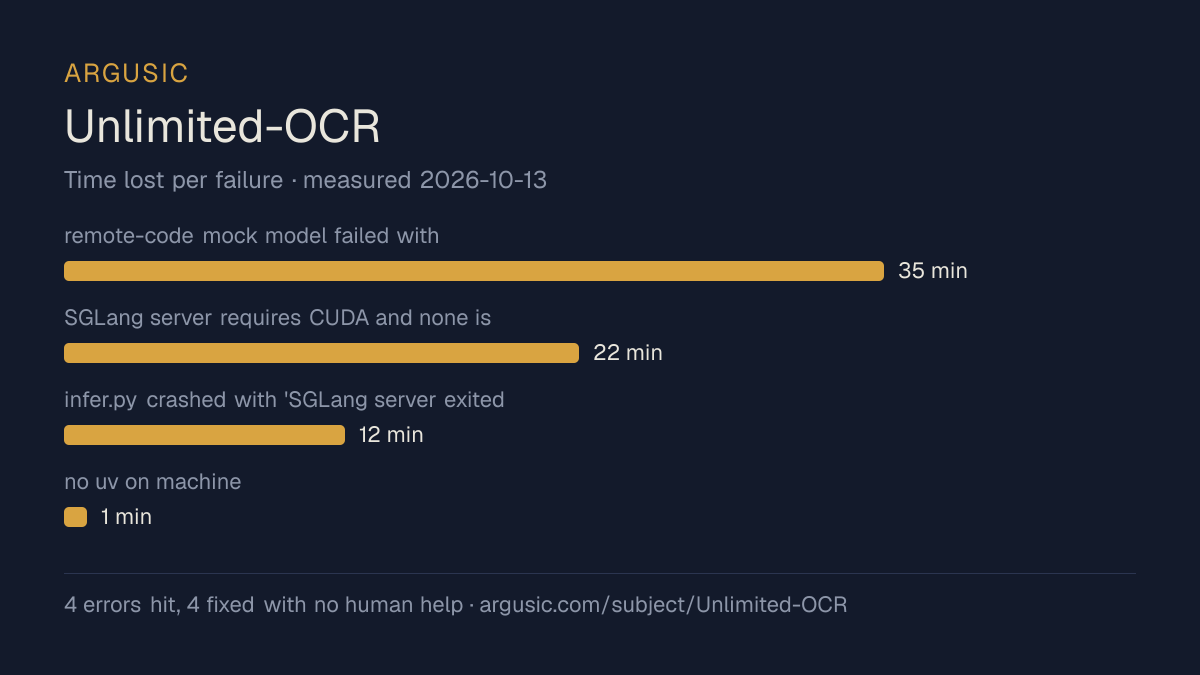
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- remote-code mock model failed with DynamicCache error, tuple output, missing ModelOutput import, and malformed tokenizer.json35 minutes
- SGLang server requires CUDA and none is present22 minutes
- infer.py crashed with 'SGLang server exited early' even though a healthy server was already up12 minutes
- no uv on machine1 minute
- Install time
- 8 minutes
- Cold machine to finish
- 14 minutes
- Errors hit and fixed
- 4 hit, 4 fixed with no human help
- How the result was proved
- python infer.py --image_dir /tmp --output_dir /tmp/out_imgs --concurrency 4 --image_mode gundam -> Requests 1/1, Total tokens 8; python infer.py --pdf ./Unlimited-OCR.pdf --output_dir /tmp/out_pdf --concurrency 2 --image_mode base -> Requests 14/14, Total tokens 112; ffmpeg -v error -f null - returned no decode errors on both PNG and GIF assets
- Model tokens used
- 577,758
- Exact commit tested
- 92ad94b53a51
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
- SGLang server cannot start without a GPU (expected) → mocked a real SGLang-style HTTP endpoint so…
- When a healthy server was already present, `infer.py` still crashed with "SGLang server exited ea…
- The standalone remote-code mock model needed `auto_map`, a working `DynamicCache`-compliant `forw…
**Verified facts**
- `infer.py --image_dir /tmp --output_dir /tmp/out_imgs --concurrency 4 --image_mode gundam` → `Req…
- `infer.py --pdf ./Unlimited-OCR.pdf --output_dir /tmp/out_pdf --concurrency 2 --image_mode base` …
- `ffmpeg -v error -i /tmp/doc.png -f null -` and `ffmpeg -v error -i assets/long-horizon-ocr.gif -…
- Real network access to the model exists (HF API lists the weights, 6.7 GB single safetensor), so …
**Record of what the mock is vs. what can't be verified**
- The mock is a hand-written FastAPI server emulating the SGLang SSE contract on port 10000. The cl…
- What is NOT verified: any real OCR output, any real GPU inference, the SGLang server boot. Those …
`install_succeeded=true`, `launch_succeeded=true` (client tool ran; the SGLang server itself cannot…
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Recovered from all 4 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed MIT, as reported by its host.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Took 8 minutes to install, slower than the median of the 41 comparable projects Argusic has measured.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Of the 42 Python projects Argusic has installed and timed, Unlimited-OCR was the 29th fastest to reach a running state, and 21 of 42 reached one at all.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.14 |
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/unlimited-ocr)Questions
- Does Unlimited-OCR run?
- Unlimited-OCR runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 8 minutes, hitting 4 errors on the way, and recorded the session.
- How did Argusic test Unlimited-OCR?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 92ad94b53a51. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test Unlimited-OCR?
- The run that produced this verdict cost $0.14: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does Unlimited-OCR take to install?
- 8 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does Unlimited-OCR need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing Unlimited-OCR?
- 4 things broke in the recorded run, and 4 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does Unlimited-OCR compare with the alternatives?
- Of the 42 Python projects Argusic has installed and timed, Unlimited-OCR was the 29th fastest to reach a running state, and 21 of 42 reached one at all.
- Where is the evidence for Unlimited-OCR?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.