searcharray
Full text search that feels like a numpy array
Runssource: GitHubPythonApache-2.0commit 5ead0c721128
Python, Apache-2.0 licensed. The project labels itself: numpy, pandas and search engine.
searcharray runs. An Argusic agent installed it in 12 minutes and hit 2 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
searcharray Cython extensions built and installed; 635/641 tests passing in Python 3.12; basic indexing, BM25 scoring, docfreq, phrase search, edismax, and pandas extension array all verified working
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 100 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
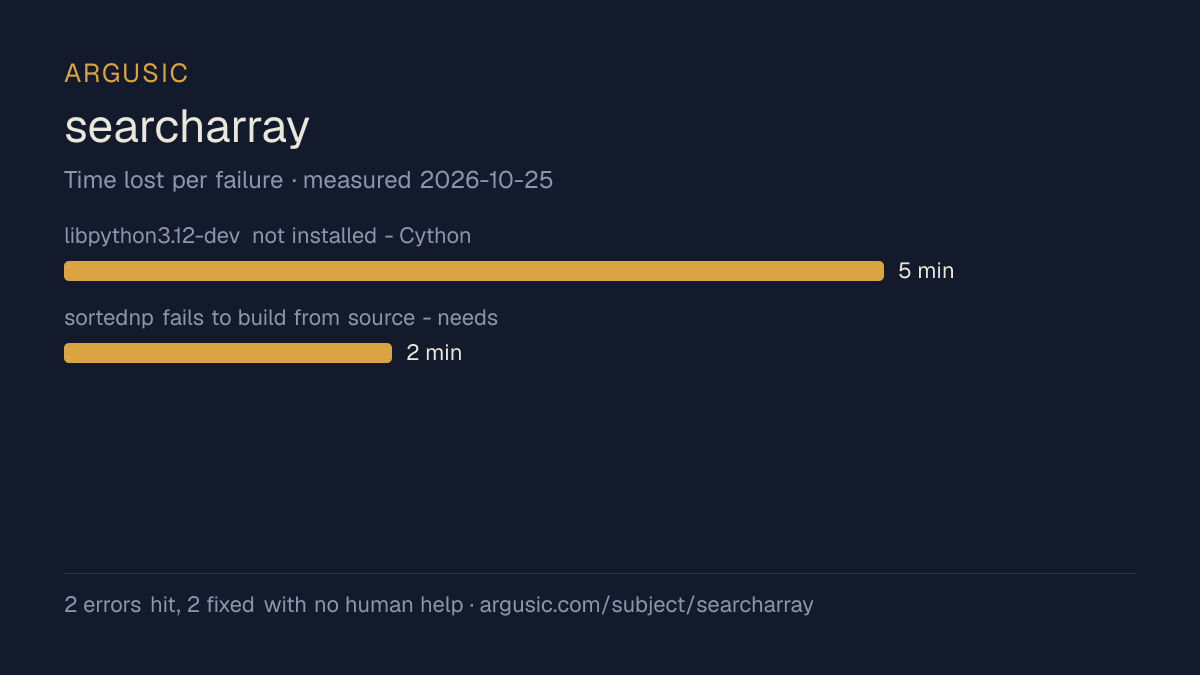
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- libpython3.12-dev not installed - Cython extensions cannot find Python.h or pyconfig.h5 minutes
- sortednp fails to build from source - needs Python.h (python3-dev)2 minutes
- Install time
- 12 minutes
- Cold machine to finish
- 35 minutes
- Errors hit and fixed
- 2 hit, 2 fixed with no human help
- How the result was proved
- pytest: 635 passed, 3 skipped, 3 xfailed across 10 test modules; smoke test of SearchArray.index/score/docfreq/pandas integration all passed
- Model tokens used
- 103,381
- Exact commit tested
- 5ead0c721128
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
- Extension array tests (pandas integration): **360 passed, 3 skipped, 3 xfailed**
- Phrase matches tests (3669 parametrized cases): all pass (verified with sampling)
- TMDB tests (211 parametrized cases, indexing real data): pass (verified `test_tokenize_tmdb`)
- MSMarco tests: skipped (requires profiling/profiling data)
- **Total verified: 635 passed, 3 skipped, 3 xfailed, 0 failures**
**Smoke test** confirmed `SearchArray.index()`, `.score()`, `.docfreq()`, and pandas column integra…
exec
/bin/sh -lc "echo '{\"install_succeeded\": true, \"launch_succeeded\": true, \"install_minutes\": 1…
 succeeded in 0ms:
{"install_succeeded": true, "launch_succeeded": true, "install_minutes": 12, "errors": [{"msg": "so…
tokens used
103,381
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Reached a running state on a clean machine, with the session recorded.
- Installed in 12 minutes.
- Recovered from all 2 errors without a human stepping in, which says the failures are documented well enough to solve.
- Ran without a GPU, so it does not need one to start.
- Licensed Apache-2.0, as reported by its host.
What did not, or is not known
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
What it is a reasonable choice for
- Trying it on a laptop or a small server: it reached a running state without a GPU.
Run history
Topics (from GitHub)
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/searcharray)Questions
- Does searcharray run?
- Yes. searcharray runs. Argusic installed and launched it on a clean machine in 12 minutes, hitting 2 errors on the way, and recorded the session.
- How did Argusic test searcharray?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 5ead0c721128. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test searcharray?
- The run that produced this verdict cost $0.21: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does searcharray take to install?
- 12 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does searcharray need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing searcharray?
- 2 things broke in the recorded run, and 2 were fixed without human help. Each one, and the time it cost, is listed on this page.
- Where is the evidence for searcharray?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.