claude-vibe-squad
Markdown-first orchestration for 71 specialists across Codex, Claude, Gemini, and Grok. Chrono coordinates scoped tasks in isolated git worktrees, with tests, cross-family review when triggered, and private Markdown memory. Runs locally in tmux.
Not yet verifiedsource: GitHubPythonMITcommit 5392a48276bb
Python, MIT licensed. The project labels itself: agent orchestration, ai agents, bash, claude code, cli, developer tools, dogfooding and human in the loop.
claude-vibe-squad has not been verified yet.
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 50 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page. Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the most recent recorded attempt, which did not reach a verdict. Every line is a recorded value, not an estimate.
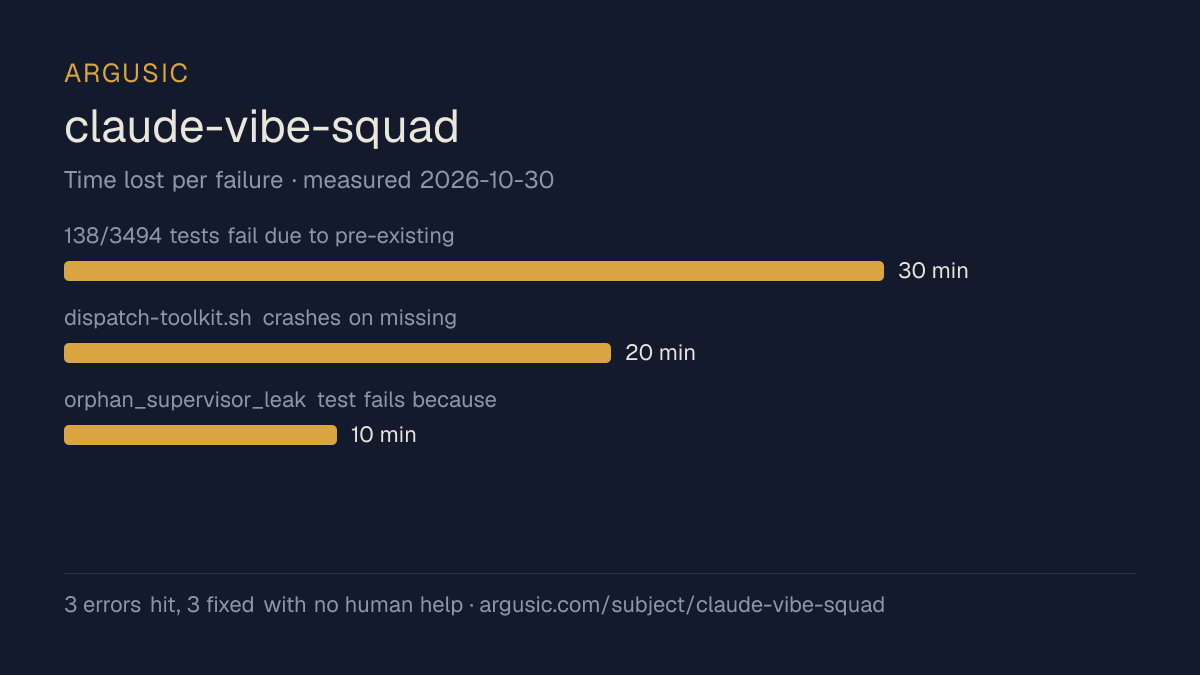
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- 138/3494 tests fail due to pre-existing macOS-only CLI paths (/opt/homebrew/bin/codex) and missing private files (skill-tool-registry.tsv, chrono-dedup, target_scan.py). Not fixable on Linux without the macOS binaries and private repository.30 minutes
- dispatch-toolkit.sh crashes on missing private registry file shared/registries/skill-tool-registry.tsv (not shipped in public repo)20 minutes
- orphan_supervisor_leak test fails because SQUAD_BASE_BRANCH not set in test env, supervisor exits 74 instead of expected 7510 minutes
- Install time
- 1 minutes
- Cold machine to finish
- 45 minutes
- Errors hit and fixed
- 3 hit, 3 fixed with no human help
- How the result was proved
- SQUAD_CI_HOST_INDEPENDENT=1 .venv/bin/python -m pytest scripts/python/tests/test_board_dispatch.py::BoardDispatchShellTests::test_prepared_ordinary_and_review_packets_reach_hardened_dry_run scripts/python/tests/orphan_supervisor_leak_test.py::OrphanSupervisorLeakTests::test_real_supervisor_exits_when_vault_root_disappears tests/ -q returned '51 passed, 3 skipped, 26 subtests passed'
- Model tokens used
- 2,564,070
- Exact commit tested
- 5392a48276bb
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
The test_prepared_ordinary_and_review_packets needs `SQUAD_CI_HOST_INDEPENDENT=1` because it runs t…
exec
/bin/sh -lc 'cd /work/repo && PATH="$HOME/.local/bin:$PATH" SQUAD_CI_HOST_INDEPENDENT=1 .venv/bin/p…
 succeeded in 24226ms:
...........................................s... [ 90%]
.....                                                                 [100%]
51 passed, 3 skipped, 26 subtests passed in 24.17s
All passing.
2026-10-30T20:55:35.612815Z ERROR codex_core::session: failed to record rollout items: thread 01a18…
tokens used
2,564,070
All passing.
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Did not run | 50.00 | 0.62 |
Topics (from GitHub)
agent-orchestrationai-agentsbashclaude-codeclideveloper-toolsdogfoodinghuman-in-the-loopllm-orchestrationlocal-firstmarkdownmcpmodel-context-protocolmulti-agentmulti-modelopenai-codextmuxworkflow-automation
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/claude-vibe-squad)Questions
- Does claude-vibe-squad run?
- claude-vibe-squad has not been fully verified yet. No recorded run has produced a verdict yet.
- How did Argusic test claude-vibe-squad?
- On a fresh, disposable machine, with every command recorded. One attempt is recorded, and the full method is on the methodology page.
- Where is the evidence for claude-vibe-squad?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.