AI-Cross-Border-Ecommerce-Agent-Toolkit
AI 跨境电商运营智能体工具箱 · 把运营 SOP 拆成 7 个可复用的 AI Agent 工作流,含 Prompt、模板与真实案例
Runssource: GitHubPythonMITcommit 0c7b2ded6325
Python, MIT licensed. The project labels itself: ai agents, cross border ecommerce, ecommerce, llm, mercado livre, prompt engineering, shopee and sop.
AI-Cross-Border-Ecommerce-Agent-Toolkit runs. An Argusic agent installed it in 2 minutes and hit 1 error and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
8 Python automation scripts (market research, pricing, title linting, spec consistency, ad metrics, image check) run on Python 3.12.3 with only Pillow as additional dependency, processing sample data end-to-end with correct structured output.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 100 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
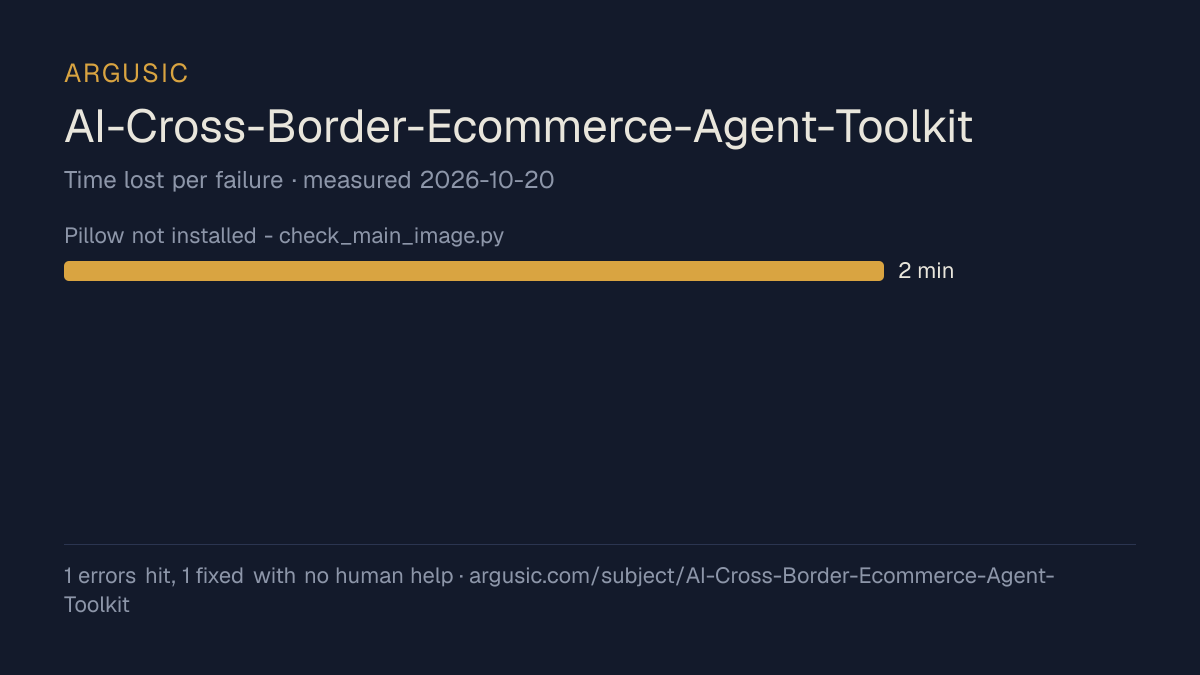
- Pillow not installed - check_main_image.py depends on it2 minutes
- Install time
- 2 minutes
- Cold machine to finish
- 5 minutes
- Errors hit and fixed
- 1 hit, 1 fixed with no human help
- How the result was proved
- All 8 Python scripts run against real/sample data, all exited code 0 producing correct outputs: shaduola_parser.py normalized CSV to JSON (10 fields), market_metrics.py computed metrics (capacity/concentration/price bands/config matrix), sku_pricing.py calculated margins/break-even prices, title_lint.py checked title compliance, spec_consistency.py verified parameter traceability, ad_metrics.py computed cost model and diagnosed campaigns, check_main_image.py validated image compliance across Shopee/ML/Amazon, make_sample.py generated synthetic data
- Model tokens used
- 64,137
- Exact commit tested
- 0c7b2ded6325
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
03. market_metrics.py: Market capacity, concentration, price bands, config matrix - PASS
04. sku_pricing.py: Margin calc, break-even/target price, SKU matrix - PASS
05. title_lint.py: Character count, forbidden words, keyword coverage, locale - PASS
06. spec_consistency.py: Spec table → copy number traceability - PASS
07. ad_metrics.py: Cost model, campaign diagnosis, P0/P1/P2 grading - PASS
08. check_main_image.py: Size, square, coverage, white bg, uniformity checks - PASS
Dependency: Pillow installed for image analysis. Rest use stdlib only.
Sample data: Pre-built CSV + normalized JSON in repo, all processable end to end.
All 8 scripts verified successfully. Let me provide the final result.
tokens used
64,137
All 8 scripts verified successfully. Let me provide the final result.
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Reached a running state on a clean machine, with the session recorded.
- Installed in 2 minutes, faster than the median of the 85 comparable projects Argusic has measured.
- Recovered from all 1 error without a human stepping in, which says the failures are documented well enough to solve.
- Ran without a GPU, so it does not need one to start.
- Licensed MIT, as reported by its host.
What did not, or is not known
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Of the 86 ai-agents projects Argusic has installed and timed, AI-Cross-Border-Ecommerce-Agent-Toolkit was the 17th fastest to reach a running state, and 65 of 86 reached one at all.
What it is a reasonable choice for
- Trying it on a laptop or a small server: it reached a running state without a GPU.
- A quick evaluation: it was running 2 minutes after the clone.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
Topics (from GitHub)
ai-agentscross-border-ecommerceecommercellmmercado-livreprompt-engineeringshopeesopworkflow-automation
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/ai-cross-border-ecommerce-agent-toolkit)Questions
- Does AI-Cross-Border-Ecommerce-Agent-Toolkit run?
- Yes. AI-Cross-Border-Ecommerce-Agent-Toolkit runs. Argusic installed and launched it on a clean machine in 2 minutes, hitting 1 error on the way, and recorded the session.
- How did Argusic test AI-Cross-Border-Ecommerce-Agent-Toolkit?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 0c7b2ded6325. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test AI-Cross-Border-Ecommerce-Agent-Toolkit?
- The run that produced this verdict cost $0.10: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does AI-Cross-Border-Ecommerce-Agent-Toolkit take to install?
- 2 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does AI-Cross-Border-Ecommerce-Agent-Toolkit need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing AI-Cross-Border-Ecommerce-Agent-Toolkit?
- 1 thing broke in the recorded run, and 1 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does AI-Cross-Border-Ecommerce-Agent-Toolkit compare with the alternatives?
- Of the 86 ai-agents projects Argusic has installed and timed, AI-Cross-Border-Ecommerce-Agent-Toolkit was the 17th fastest to reach a running state, and 65 of 86 reached one at all.
- Where is the evidence for AI-Cross-Border-Ecommerce-Agent-Toolkit?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.