simplemind
Python API client for AI providers that intends to replace LangChain and LangGraph for most common use cases.
Runs with mockssource: GitHubPythonApache-2.0commit c3d8a0c2741c
Python, Apache-2.0 licensed. The project labels itself: ai, anthropic, anthropic claude, api client, artificial intelligence, gemini, langchain and llms.
simplemind runs, with stand-ins for the services it depends on. An Argusic agent installed it in 2.5 minutes and hit 5 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
The simplemind package installs in a Python venv and all 45 tests pass with mocked provider SDKs (OpenAI, Anthropic, Groq, Gemini, Ollama) returning canned responses for text generation, structured data generation, conversation management, tool calling, and minimax configuration.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page. Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
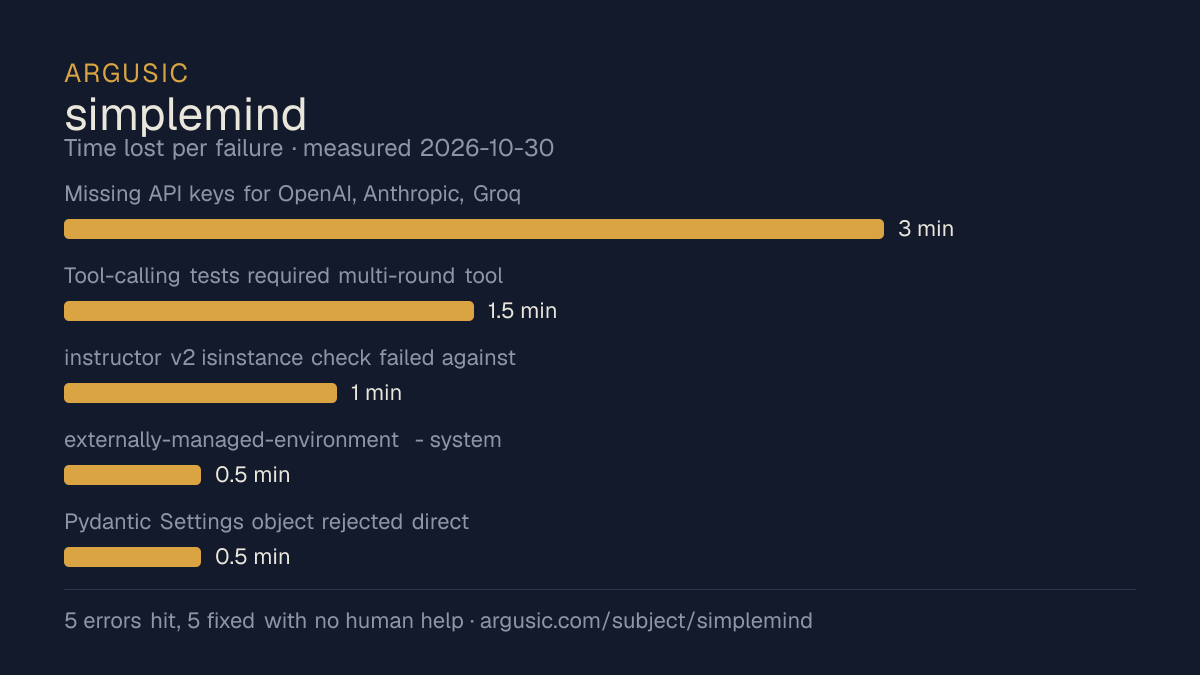
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- Missing API keys for OpenAI, Anthropic, Groq, Ollama caused ValueError or connection errors3 minutes
- Tool-calling tests required multi-round tool call simulation1.5 minutes
- instructor v2 isinstance check failed against monkeypatched constructors1 minute
- externally-managed-environment - system Python blocks pip install0.5 minutes
- Pydantic Settings object rejected direct field assignment0.5 minutes
- Install time
- 3 minutes
- Cold machine to finish
- 19 minutes
- Errors hit and fixed
- 5 hit, 5 fixed with no human help
- How the result was proved
- cd /work/repo && /tmp/sm-venv/bin/python -m pytest tests/ -v -> 45 passed in 2.95s
- Model tokens used
- 793,850
- Exact commit tested
- c3d8a0c2741c
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
4. **instructor isinstance check failed** - instructor v2 does isinstance checks on client objects …
   - Fix: Used real SDK instances with monkeypatched methods instead of replacing the class constru…
5. **Tool calling loop** - tool tests required multiple API call rounds
   - Fix: Built a `_ToolSimulator` that returns tool calls for each tool in sequence
6. **Pydantic Settings field assignment** - trying to monkeypatch Pydantic BaseSettings fields dire…
   - Fix: Use environment variables to set API keys instead
exec
/bin/sh -lc "echo '{\"install_succeeded\": true, \"launch_succeeded\": true, \"install_minutes\": 2…
 succeeded in 0ms:
{"install_succeeded": true, "launch_succeeded": true, "install_minutes": 2.5, "errors": [{"msg": "e…
tokens used
793,850
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Installed in 2.5 minutes, faster than the median of the 226 comparable projects Argusic has measured.
- Recovered from all 5 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed Apache-2.0, as reported by its host.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Of the 227 ai projects Argusic has installed and timed, simplemind was the 67th fastest to reach a running state, and 148 of 227 reached one at all.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.17 |
Topics (from GitHub)
aianthropicanthropic-claudeapi-clientartificial-intelligencegeminilangchainllmsopenaiopenai-api
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/simplemind)Questions
- Does simplemind run?
- simplemind runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 3 minutes, hitting 5 errors on the way, and recorded the session.
- How did Argusic test simplemind?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit c3d8a0c2741c. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test simplemind?
- The run that produced this verdict cost $0.17: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does simplemind take to install?
- 2.5 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does simplemind need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing simplemind?
- 5 things broke in the recorded run, and 5 were fixed without human help. Each one, and the time it cost, is listed on this page.
- How does simplemind compare with the alternatives?
- Of the 227 ai projects Argusic has installed and timed, simplemind was the 67th fastest to reach a running state, and 148 of 227 reached one at all.
- Where is the evidence for simplemind?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.