MOSS-TTSD
A multilingual model for long-form, multi-speaker dialogue synthesis with flexible speaker control and zero-shot voice cloning
Runssource: GitHubhomepagePythonApache-2.0commit 46973e425da2
Python, Apache-2.0 licensed. The project labels itself: finetune, large language models, multilingual, podcast, sglang, speech dialogue generation, speech synthesis and streaming.
MOSS-TTSD runs. An Argusic agent installed it in 6 minutes and hit 2 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
MOSS-TTSD v1.0 model loads from HuggingFace, processor encodes conversations, forward pass returns logits, and generate() produces audio codes and text tokens on CPU with bfloat16 precision
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 100 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
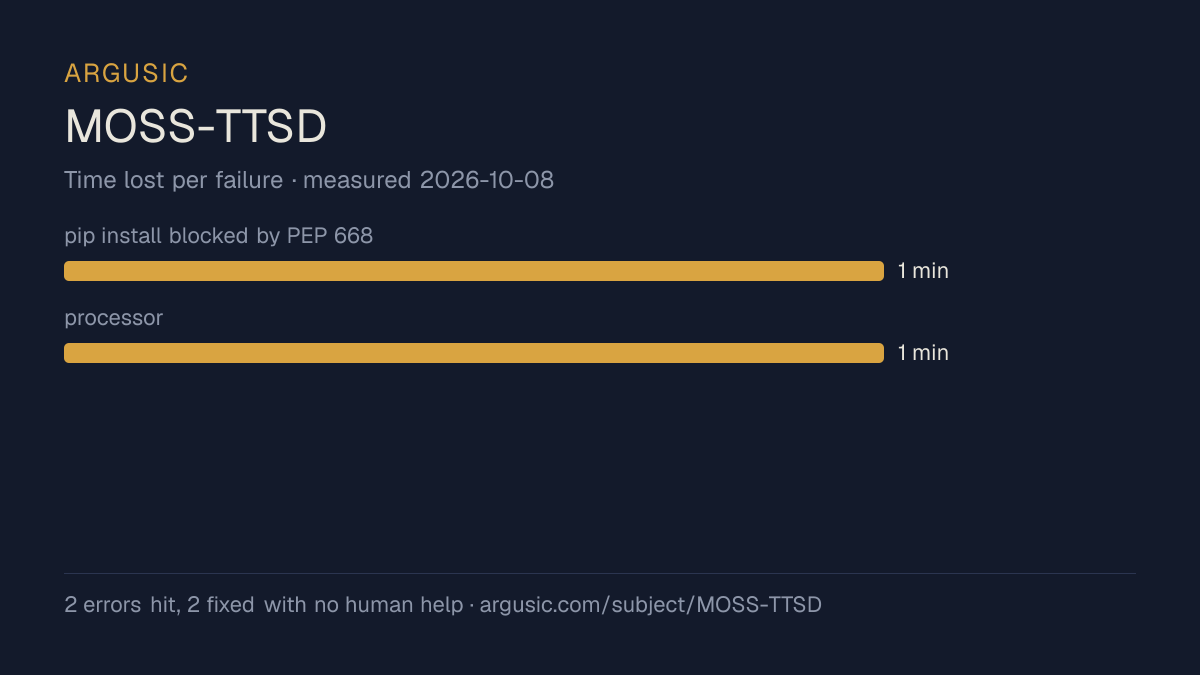
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- pip install blocked by PEP 668 (externally-managed-environment) on Debian-based container1 minute
- processor(text=...) kwarg raised KeyError: conversations1 minute
- Install time
- 6 minutes
- Cold machine to finish
- 25 minutes
- Errors hit and fixed
- 2 hit, 2 fixed with no human help
- How the result was proved
- python3 -c '... model.generate(...)' returned audio_codes (shape [5, 17]) and text_tokens (shape [5, 17]) tensors after 5 generation steps; forward pass returned logits
- Model tokens used
- 51,873
- Exact commit tested
- 46973e425da2
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
    ],
    \"test_depth\": \"tier1_real\",
    \"notes\": \"End-to-end verification with actual HuggingFace model weights (OpenMOSS-Team/MOSS-…
    \"verified_how\": \"python3 -c '... model.generate(...)' returned audio_codes (shape [5, 17]) a…
    \"final_state\": \"MOSS-TTSD v1.0 model loads from HuggingFace, processor encodes conversations…
}
print(json.dumps(result))
PYEOF" in /work/repo
 succeeded in 0ms:
{"install_succeeded": true, "launch_succeeded": true, "install_minutes": 6, "errors": [{"msg": "pip…
tokens used
51,873
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Reached a running state on a clean machine, with the session recorded.
- Installed in 6 minutes.
- Recovered from all 2 errors without a human stepping in, which says the failures are documented well enough to solve.
- Ran without a GPU, so it does not need one to start.
- Licensed Apache-2.0, as reported by its host.
What did not, or is not known
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
What it is a reasonable choice for
- Trying it on a laptop or a small server: it reached a running state without a GPU.
- A quick evaluation: it was running 6 minutes after the clone.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
Topics (from GitHub)
finetunelarge-language-modelsmultilingualpodcastsglangspeech-dialogue-generationspeech-synthesisstreamingtext-to-speechvoice-cloning
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/moss-ttsd)Questions
- Does MOSS-TTSD run?
- Yes. MOSS-TTSD runs. Argusic installed and launched it on a clean machine in 6 minutes, hitting 2 errors on the way, and recorded the session.
- How did Argusic test MOSS-TTSD?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit 46973e425da2. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test MOSS-TTSD?
- The run that produced this verdict cost $0.07: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does MOSS-TTSD take to install?
- 6 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does MOSS-TTSD need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing MOSS-TTSD?
- 2 things broke in the recorded run, and 2 were fixed without human help. Each one, and the time it cost, is listed on this page.
- Where is the evidence for MOSS-TTSD?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.