meetingly-ai
Open-source AI interview assistant and meeting copilot: live answers during Zoom, Google Meet and Teams calls, on-device transcription, hidden from screen sharing. Free Cluely, Interview Coder and Final Round AI alternative for Windows, macOS, Linux.
Runs with mockssource: GitHubhomepageTypeScriptApache-2.0commit e55cc045e18a
TypeScript, Apache-2.0 licensed. The project labels itself: ai interview assistant, ai meeting assistant, cluely, cluely alternative, cluely clone, coding interview, electron and final round ai.
meetingly-ai runs, with stand-ins for the services it depends on. An Argusic agent installed it in 13 minutes and hit 5 errors and fixed every one without help on a clean machine with no GPU, and the whole session was recorded.
The app installs and builds on the bundled toolchain, 123 unit tests and 44 relay tests pass, the Electron app launches (windows visible on Xvfb), and a chat request travels from the built app through the local relay to the OpenAI-compatible mock upstream and back with HTTP 200.
What the agent ended up with on a clean machine, in its own words. How this is measured
Measured by Argusic on a fresh machine every time. Every number links to its evidence. Argusic Score 92 of 100 (the mean of this project's run scores).
At a glance
Subject data from GitHub, linked at the top of this page, refreshed . Test data by Argusic (CC BY 4.0); every number links to a run page with the full log, the recording, and their sha256 hashes.
What was measured
From the run that decided this verdict. Every line is a recorded value, not an estimate.
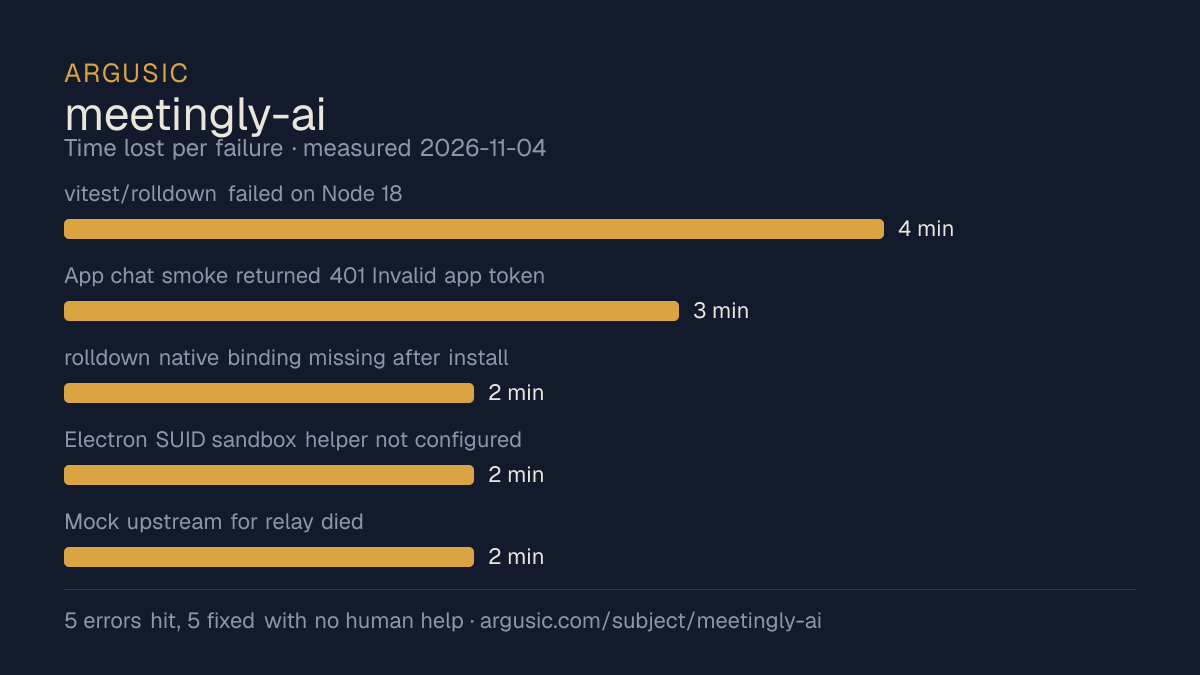
What went wrong, in the agent's own words
The agent's own words, worst first, never rewritten into advice.
- vitest/rolldown failed on Node 18: node:util has no styleText export4 minutes
- App chat smoke returned 401 Invalid app token against my mock relay3 minutes
- rolldown native binding missing after install (npm optional-deps bug)2 minutes
- Electron SUID sandbox helper not configured (no root in container)2 minutes
- Mock upstream for relay died (bad empty-body handling in my first mock on Node 18)2 minutes
- Install time
- 13 minutes
- Cold machine to finish
- 10 minutes
- Errors hit and fixed
- 5 hit, 5 fixed with no human help
- How the result was proved
- npm test (Node 22): 16 files, 123 tests passed; relay npm test: 44/44 passed; relay /health HTTP 200 {ok:true,version:2.4.1}; POST /v1/chat/completions HTTP 200 with mock reply and usage counted; app smoke: windows visible, errors [] and smoke chat ok:true; packaged binary stayed up 60s
- Model tokens used
- 602,705
- Exact commit tested
- e55cc045e18a
- Container image
- sha256:cdd920bce783
What was not measured
The other half, so you can see exactly how far this evidence goes. A gap is printed as a gap and never filled in.
- Peak GPU memory
- this ran on a CPU machine, so there was no GPU to sample
- Behaviour over a long run
- each attempt uses the smallest documented settings and a fixed time budget, so this measures whether it runs, not how it holds up under load
- Behaviour against real services
- this run was verified against stand-in services only
The end of the recording
The last lines of the terminal session that decided this verdict, exactly as they were recorded.
2. `rolldown` native binding missing (`@rolldown/binding-wasm32-wasi`): npm 9's known optional-deps…
   Fix: reinstall `node_modules` under Node 22. Verified: tests pass, `npm run build` exits 0.
3. Electron SUID sandbox: `chrome-sandbox` not owned by root/mode 4755 (container has no root).
   Fix: `ELECTRON_DISABLE_SANDBOX=1` (standard container workaround). Verified: smoke reports and b…
4. Mock upstream died mid-run — my first mock used container Node 18 and crashed on an empty reques…
5. `smoke chat` initially returned 401 `"Invalid app token"` — the relay is the mock-backed one I s…
**Verified final state**
- `app`: `npm test` under Node 22 → `Test Files 16 passed (16)`, `Tests 123 passed (123)`; `npm run…
- `relay`: `npm test` → `44 pass, 0 fail` (including the HTTP regression test with a fixture upstre…
- App→relay→mock full flow: `IGPT_RELAY_URL=http://127.0.0.1:18090 ELECTRON_DISABLE_SANDBOX=1 node …
- Not exercised (recorded gap, not an error): the on-device ASR engine (`npm run fetch:asr` downloa…
One note: the repo now has no uncommitted changes (I restored npm's cosmetic rewrite of `app/packag…
Replay the whole session, every command from a clean machine to this point.
How it was tested
One agent, one container, no human help. It installs the project the way its own documentation says to, runs it, and fixes what breaks. Everything below is recorded as it happened: the terminal session, the log and the exact commit. The full method.
Strengths and limits
Measured facts, not opinions. How this is written.
What went well
- Installed in 13 minutes.
- Recovered from all 5 errors without a human stepping in, which says the failures are documented well enough to solve.
- Licensed Apache-2.0, as reported by its host.
What did not, or is not known
- Only reached a running state against stand-in services, so nothing here proves it works against the real ones.
- Measured once so far. A single attempt shows it can run, not that it runs reliably.
Also tested, in the same area
Every one of these was installed and run by Argusic on a clean machine. Nothing appears here that was not tested.
Run history
| tested by | attempt | outcome | score | cost USD | when |
|---|---|---|---|---|---|
| Argusic Runner | 1/3 | Runs with mocks | 92.00 | 0.13 |
Topics (from GitHub)
ai-interview-assistantai-meeting-assistantcluelycluely-alternativecluely-clonecoding-interviewelectronfinal-round-aiinterview-assistantinterview-coderinterview-copilotllmmeeting-assistantmeeting-notesollamaopen-sourceparakeet-aipluelyspeech-to-texttranscription
Embed the badge
Markdown for the project README. It links back here; terms on the terms page.
[](https://argusic.com/subject/meetingly-ai)Questions
- Does meetingly-ai run?
- meetingly-ai runs, with mocks standing in for external services. Argusic installed and launched it on a clean machine in 13 minutes, hitting 5 errors on the way, and recorded the session.
- How did Argusic test meetingly-ai?
- On a fresh, disposable machine, with every command recorded and the repository pinned at commit e55cc045e18a. One attempt is recorded, and the full method is on the methodology page.
- What did it cost to test meetingly-ai?
- The run that produced this verdict cost $0.13: real compute and model cost, not a list price per million tokens. It is recorded on that run's page.
- How long does meetingly-ai take to install?
- 13 minutes in the run that decided this verdict, from a clean machine to a running state. That is one measured attempt, not an average.
- Does meetingly-ai need a GPU?
- Not to start. Argusic reached a running state on a machine with no GPU.
- What goes wrong when installing meetingly-ai?
- 5 things broke in the recorded run, and 5 were fixed without human help. Each one, and the time it cost, is listed on this page.
- Where is the evidence for meetingly-ai?
- The recorded run is on this page, each linking to its full log and terminal recording, stored with a sha256 fingerprint so it cannot be quietly altered.